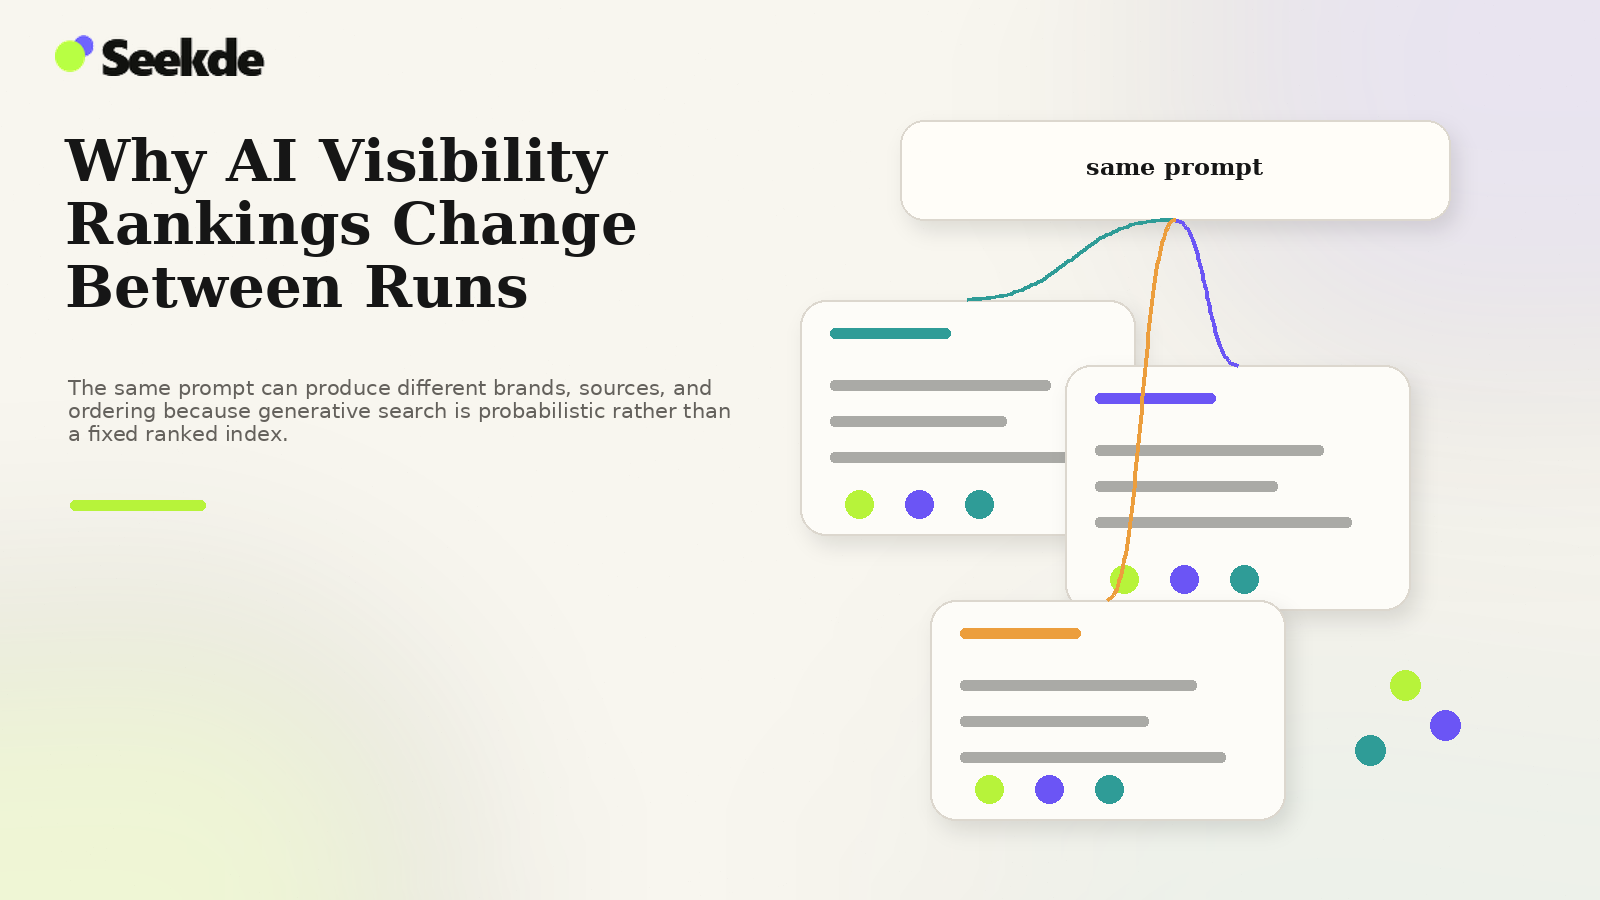
AI visibility rankings change between runs because generative search systems are probabilistic: retrieval results, model sampling, routing, source availability, and other runtime conditions can vary even when the prompt stays the same. A single ranking is therefore only one observation; reliable monitoring calls for repeated runs and stability measures rather than treating one result as a fixed position.
In traditional organic search, entering the same keyword five times into a clean browser yields virtually identical rankings on Google’s ten blue links. In generative answer engines like ChatGPT Search, Perplexity, Google AI Overviews, and Microsoft Copilot, however, entering the identical prompt five minutes apart frequently produces different narrative text, altered recommendation sequences, and entirely different cited sources.
This volatility is not an analytical tracking error. It is a fundamental consequence of how generative AI search operates: coupling non-deterministic neural language generation with dynamic, multi-step retrieval pipelines. Understanding the technical drivers of this volatility is essential for preventing false panic, establishing reliable measurement baselines, and distinguishing normal statistical jitter from systemic visibility loss.
Deterministic Indexes vs. Stochastic Generative Synthesis
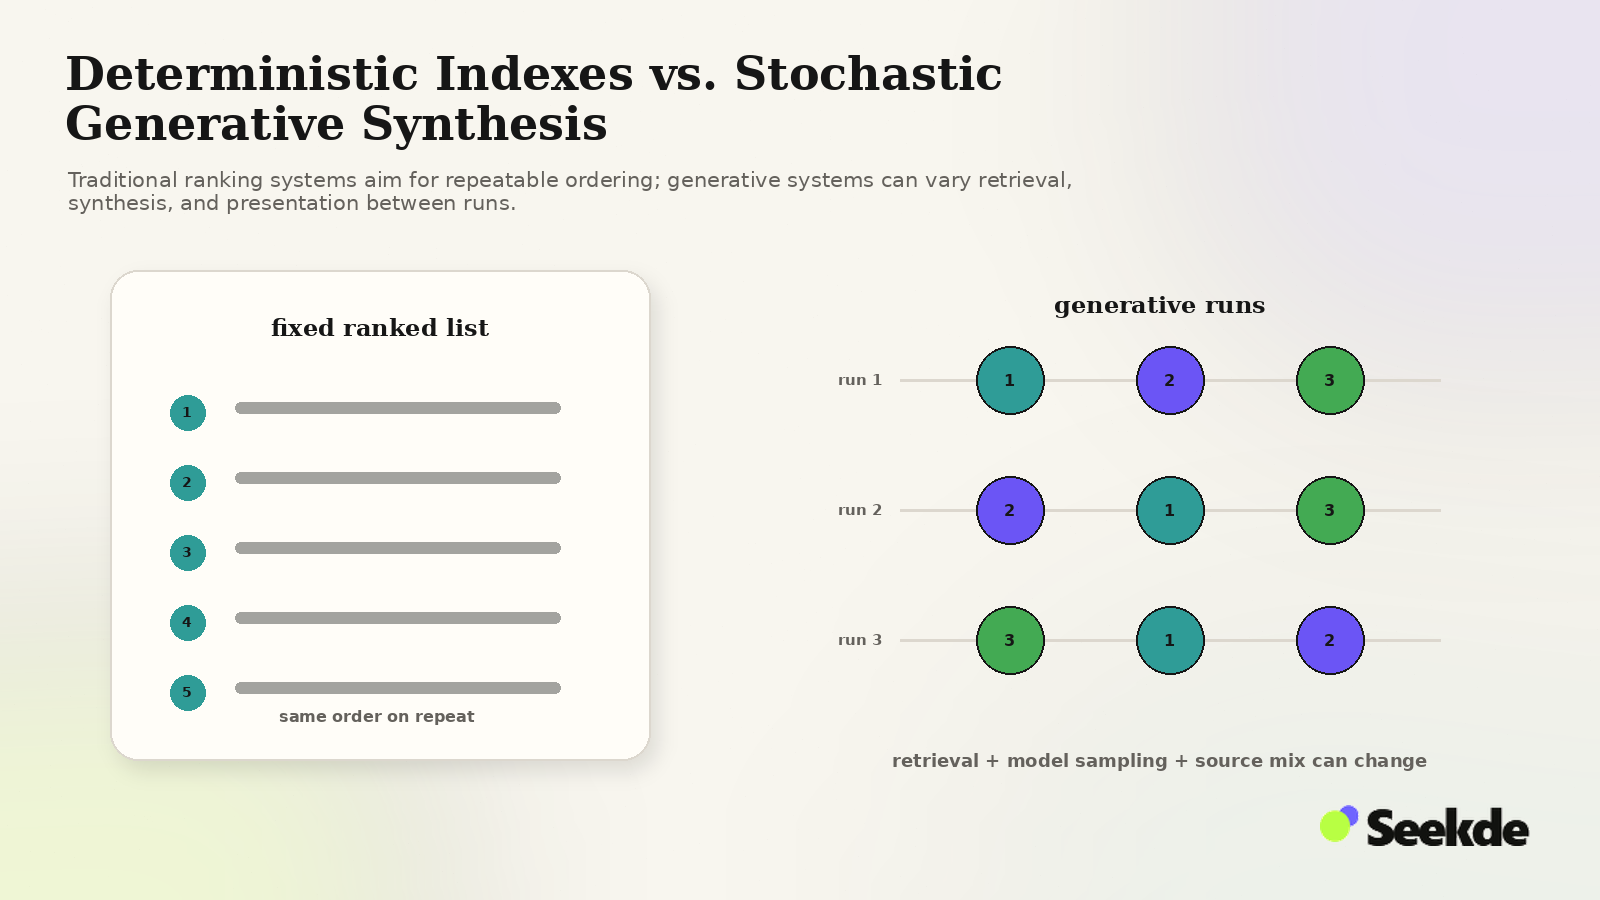
To understand volatility, search teams must contrast the mechanics of legacy search against generative retrieval:
| Dimension | Legacy Search Engine (Google Organic) | Generative AI Search Engine (RAG) |
|---|---|---|
| Underlying Architecture | Inverted keyword index with pre-computed page scores | Retrieval-Augmented Generation (RAG) with neural rerankers |
| Output Generation | Deterministic retrieval of stored document records | Probabilistic next-token generation from neural probability distributions |
| Result Determinism | Near 100% identical between immediate queries | Inherently non-deterministic when sampling temperature $T > 0$ |
| Retrieval Pathway | Direct matching against submitted query | Dynamic query expansion generating multiple synthetic sub-queries |
| Ranking Metric | Stable integer rank (Position 1, 2, 3) | Probabilistic presence distribution across repeated prompt runs |
In legacy search, changes in position reflect deliberate index updates, PageRank recalculations, or competitor link acquisition. In generative search, a brand’s position in a recommendation list can shift simply because the model sampled a different synonym during generation.
The Eight Technical Drivers of AI Visibility Volatility
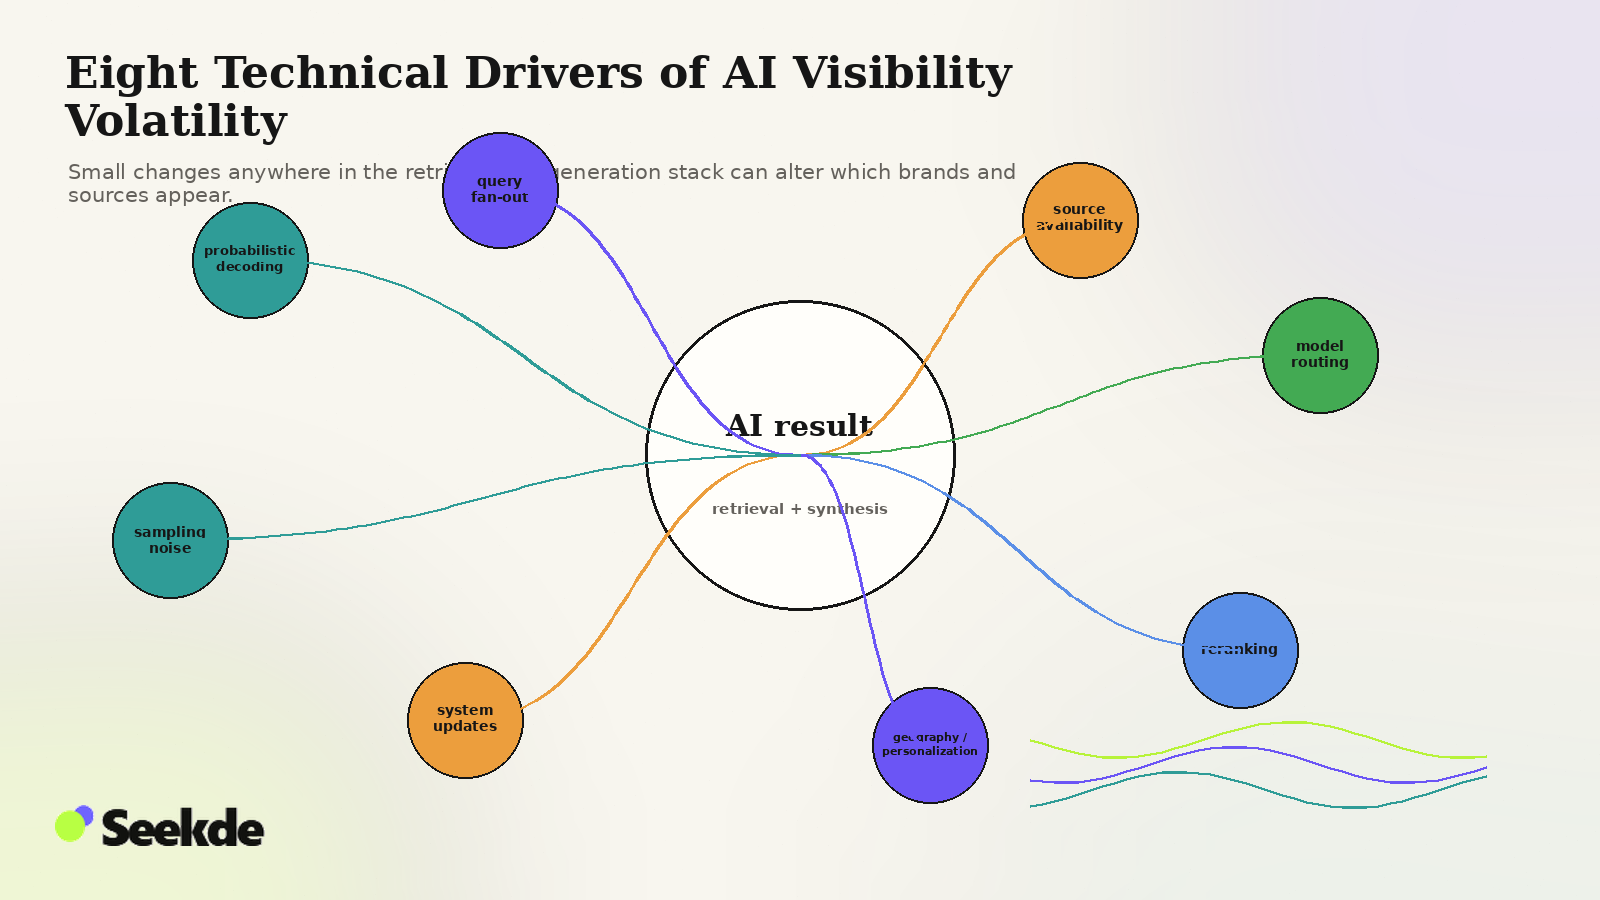
Generative ranking fluctuations stem from eight distinct technical layers operating between user prompt submission and final text rendering:
Temperature & top-p token sampling
Variable sub-query generation
Real-time crawler freshness & drops
Load-based model tier switching
Subtle cross-encoder score shifts
Token cutoffs dropping lower sources
IP routing & session context bias
DOM hydration & headless bot bugs
1. Probabilistic Next-Token Generation (Temperature and Top-$p$)
Language models do not produce text by selecting a pre-written paragraph from a database. They generate answers token-by-token, computing a probability distribution over vocabulary tokens based on the prompt and preceding text.
- Temperature ($T$): Controls the randomness of token selection. A temperature of $0.0$ forces greedy decoding (always picking the single highest-probability token). Commercial conversational search engines typically operate with non-zero temperatures to ensure natural, varied phrasing. While exact production decoding parameters remain proprietary and undisclosed, the mathematical effect of $T > 0$ is inherently stochastic.
- Top-$p$ (Nucleus Sampling): Restricts token selection to the smallest set of tokens whose cumulative probability exceeds threshold $p$.
Because temperature is greater than zero, an engine writing a response about project management might randomly choose the word "collaborative" on Run 1 and "flexible" on Run 2. That single early token divergence alters the self-attention trajectory of the entire subsequent sentence, leading the model to cite a different vendor or highlight an alternative feature set.
2. Dynamic Query Fan-Out Variability
As detailed in our analysis of Query Fan-Out in AI Search, modern answer engines do not search the web using your raw user prompt alone. A query-expansion module decomposes the prompt into multiple targeted search queries.
Because the query-expansion module is itself an LLM, the sub-queries generated can vary between runs:
- Run 1 Sub-Queries:
best enterprise crm for consulting,lightweight crms with api access - Run 2 Sub-Queries:
top crm software professional services,consulting agency client management tools
These slight variations in sub-query syntax pull different raw document candidate sets into the retrieval pool, directly altering which domains are cited in the final answer.
3. Real-Time Web Index Fluctuations and Source Availability
Generative engines crawl the web continuously to maintain grounding freshness.
- Freshness Ingestion: If an industry publication releases a breaking review or a community discussion gains significant engagement, retrieval models may ingest and elevate that page within hours, temporarily displacing established corporate documentation.
- Operational Fetch Failures: If a publisher’s web server experiences a latency spike, a 504 gateway timeout, or an automated bot challenge during the engine’s real-time retrieval window (which typically allows only a brief latency budget for live fetching), the retrieval crawler discards that URL and falls back to an alternative source.
4. Dynamic Model Routing and Latency Fallbacks
Commercial AI providers handle massive query volumes. While specific production infrastructure configurations remain proprietary, dynamic workload management—such as routing queries across different model checkpoints or adjusting retrieval depth based on latency constraints—is widely recognized in distributed systems as an operational contributor to transient output variance. Under peak cluster loads, engines may deploy lighter, distilled models with shallower context windows, shifting source inclusion patterns.
5. Neural Reranking Thresholds and Context Window Truncation
In modern two-stage retrieval architectures, a dense or lexical retriever first fetches candidate documents, after which a neural cross-encoder reranks passages by semantic relevance. The top $k$ passages are injected into the model’s context window.
While proprietary scoring thresholds are undisclosed, relevance scores across top results frequently cluster closely. Minor variations in passage chunking or sub-query relevance can push a document from rank 4 to rank 6. If the model’s context cutoff only admits the top 5 chunks, that document is completely excluded from the synthesis.
6. Geographic, Temporal, and Personalization Variables
Even when testing in unauthenticated private sessions, answer engines infer contextual signals:
- IP Geolocation: Engines route queries through regional edge nodes, subtly weighting local business entities or regional domain extensions (
.co.uk,.com.au). - Time-of-Day Caching: Major platforms deploy intermediate caching layers. Two identical queries submitted ten seconds apart may hit a cached response, while a query submitted two hours later triggers a fresh live web search.
7. Continuous Base Model Updates and RLHF Alignment
AI engineering teams continuously deploy updates:
- Safety and hallucination filter updates.
- Reinforcement Learning from Human Feedback (RLHF) adjustments penalizing overly promotional or ungrounded claims.
- Retrieval pipeline fine-tuning.
These continuous micro-updates cause gradual drift in baseline entity prominence even when a brand’s website content remains unchanged.
8. Measurement and Scraping Noise
A significant portion of reported volatility is an artifact of poor measurement tooling:
- Automated headless browser scrapers frequently fail to wait for asynchronous JavaScript hydration, missing citation cards that render after a brief delay.
- Expandable accordions are often missed by naive DOM parsers.
- IP rate limits and anti-scraping challenges cause automated trackers to log false "omissions" when the engine was actually accessible to real users.
Quantifying Volatility: Three Mathematical Stability Metrics
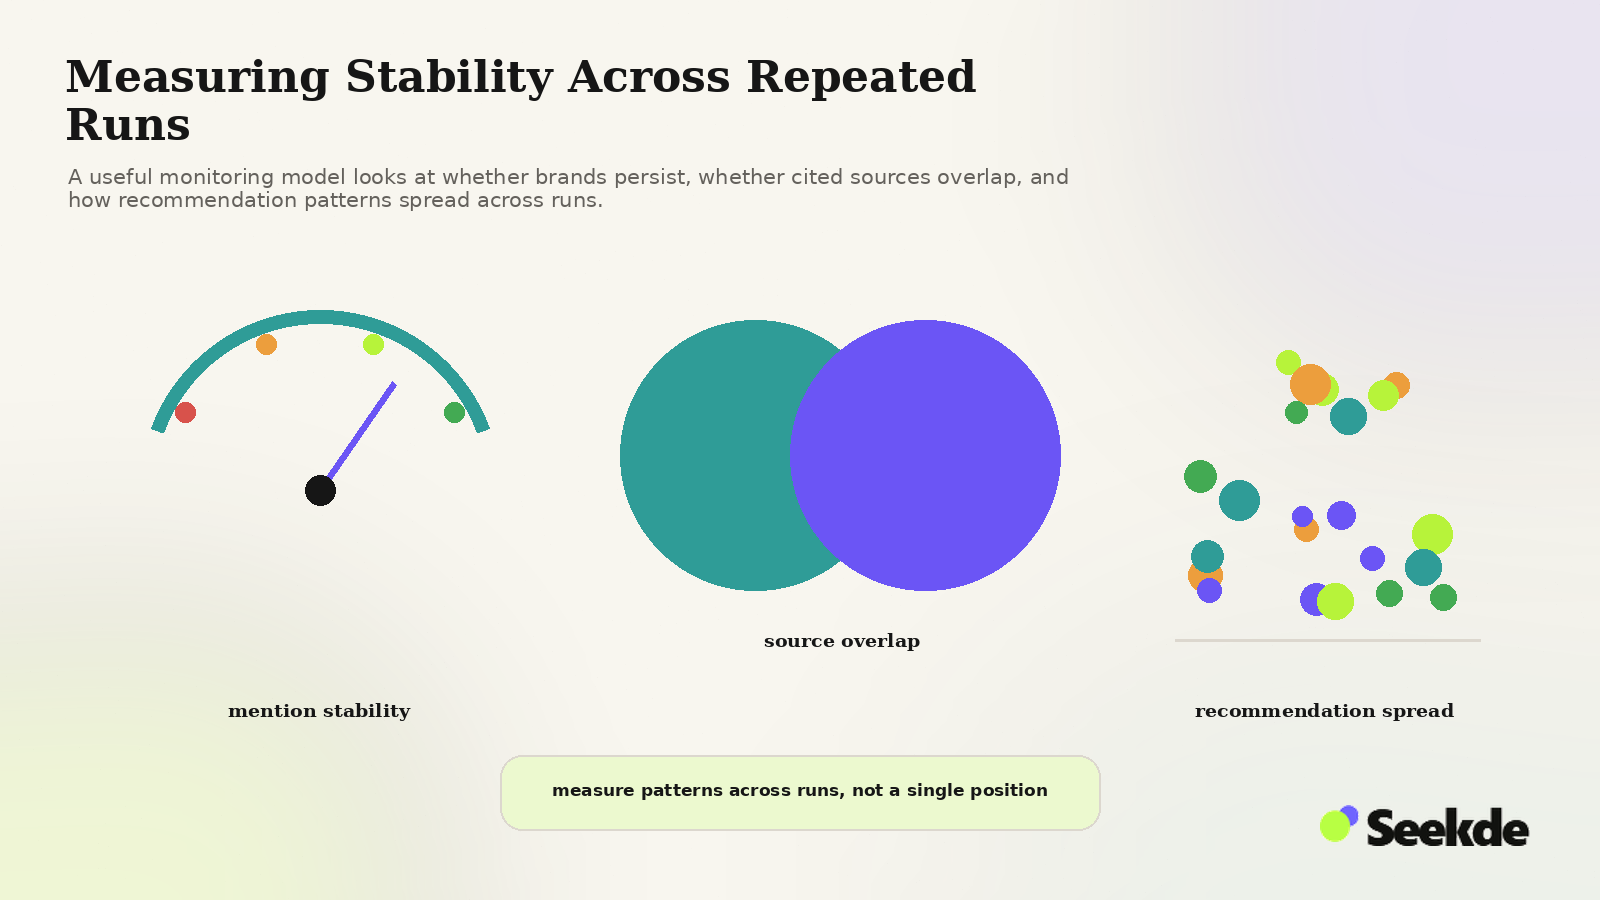
Rather than tracking single-point ranks, search teams should quantify stability using empirical probability distributions across multi-run test batches:
1. Mention Stability Rate (MSR)
The percentage of identical prompt executions where your brand is successfully named:
$$text{MSR (%)} = left( frac{text{Runs with Brand Mention}}{text{Total Valid Test Runs}} right) times 100$$
A brand with an MSR of 80% across 10 runs possesses robust foundational visibility; an MSR of 20% indicates fragile, edge-case inclusion.
2. Citation Jaccard Similarity ($J$)
Measures the consistency of the external source ecosystem cited across two separate runs ($A$ and $B$) for the same prompt:
$$J(A, B) = frac{|A cap B|}{|A cup B|}$$
Where $A$ and $B$ are the sets of unique domains cited in each run. A Jaccard index near 1.0 indicates a stable source consensus; a Jaccard index below 0.3 indicates heavy retrieval volatility.
3. Recommendation Tier Distribution
Track where your brand appears across runs:
- Tier 1 (Primary / Top 2): Core recommendation.
- Tier 2 (Alternative / Mentioned in List): Secondary consideration.
- Tier 3 (Omitted): Completely absent.
Reporting the percentage distribution across these tiers provides a realistic probabilistic representation of search presence.
How Practitioners Should Manage and Report Volatility
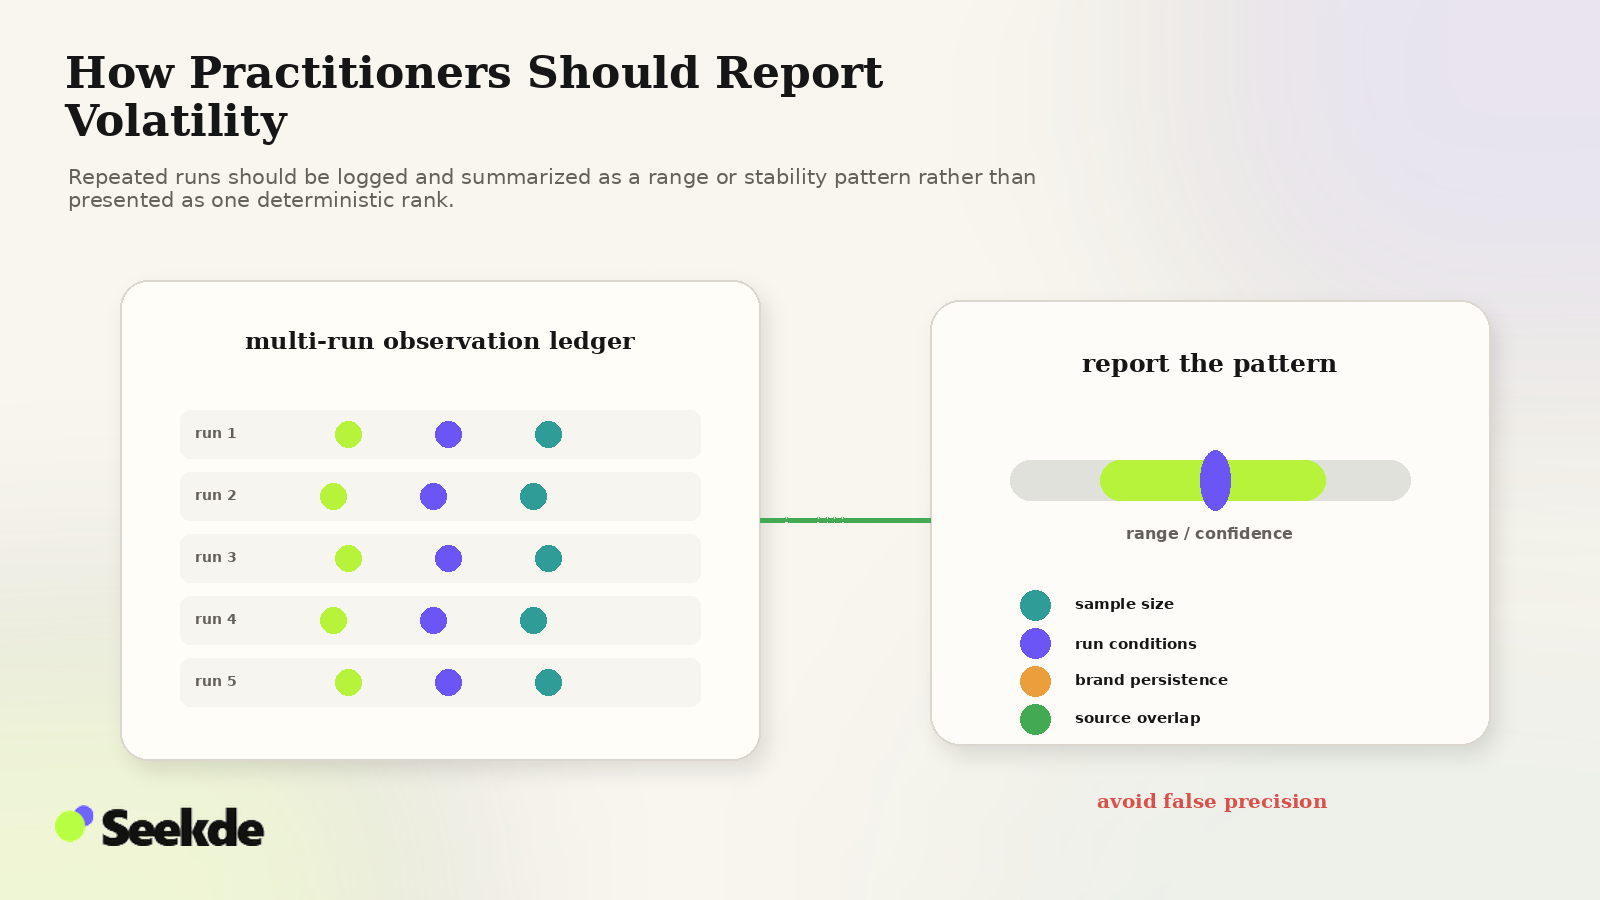
To maintain executive confidence and avoid chasing phantom algorithm shifts, search teams must implement four operational protocols:
Minimum 3–5 runs per prompt per cycle
Report 14-day or 30-day trends, not days
Distinguish transient vs systemic drops
Secure first-party and 3rd-party links
Protocol 1: Eliminate Single-Shot Audits
Never draw conclusions from a single prompt execution. As established in How to Measure Your Brand’s Visibility in AI Search, execute a minimum of three to five runs per prompt across distinct time windows before recording a baseline.
Protocol 2: Report Rolling Averages and Confidence Bands
In executive dashboards, replace daily point charts with rolling 14-day or 30-day moving averages. Display a shaded confidence band showing the range between high and low observation runs to visually communicate the natural stochasticity of generative systems.
Protocol 3: Distinguish Statistical Jitter from Systemic Loss
- Statistical Jitter: Your brand’s mention rate drops from 80% to 60% on Tuesday, but rebounds to 85% on Thursday. No action required; this is normal temperature variance.
- Systemic Loss: Your brand’s mention rate drops from 80% to 15% across all target platforms for two consecutive weeks, accompanied by a sudden loss of source citations. Immediate investigation required (check technical crawlability, robots.txt, and competitor content refreshes).
Protocol 4: Build Multi-Source Grounding Defense
Because generative models draw from diverse web sources, defend against volatility by diversifying your digital footprint. If an AI engine temporarily fails to retrieve your official product page, consistent coverage across authoritative review directories, developer documentation hubs, and industry trade journals ensures the model still finds verified ground truth to cite your brand.