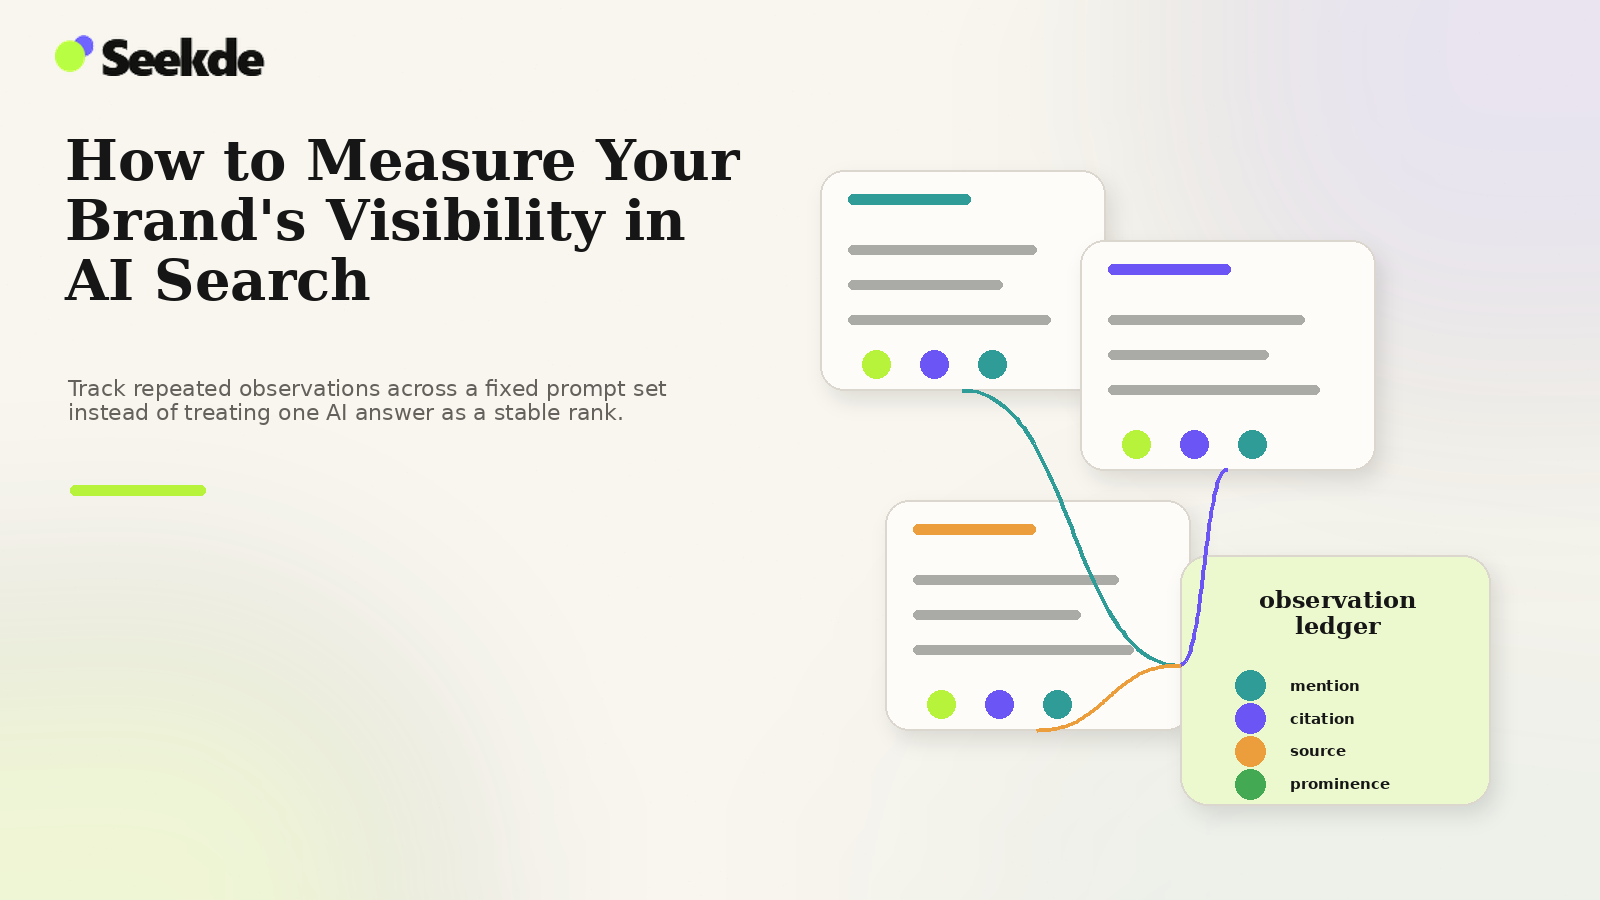
Measuring your brand’s visibility in AI search means running a fixed, representative set of prompts across selected AI platforms and recording whether the brand is mentioned or cited, which sources appear, how prominent the brand is, and how those observations change across repeated runs. The key is consistent sampling and longitudinal comparison—not treating a single AI answer as a stable rank.
Because conversational AI platforms do not publish centralized impression rankings or fixed position data, organizations cannot rely on traditional keyword rank trackers. A company cannot simply enter a keyword into a tool and receive a static ranking metric like "Position 3." Instead, evaluating an entity’s presence across Google AI Overviews, Google AI Mode, ChatGPT Search, Perplexity, and Microsoft Copilot demands an empirical framework grounded in prompt sampling, multi-run observation, and metric separation.
This guide outlines an actionable, five-stage measurement framework designed to audit and monitor AI search presence without inventing false precision.
Why Traditional Rank Tracking Fails in Generative Search
Legacy search engine rank tracking relies on three structural assumptions:
- Deterministic Output: For a given keyword in a specific location, Google renders a relatively stable set of URLs that remain consistent across multiple queries within a short timeframe.
- Fixed Positional Real Estate: Every result occupies a discrete numerical position (ranks 1 through 10) on a single vertical page.
- URL-Centric Indexing: The fundamental unit of discovery is an indexed webpage URL presented as a blue link snippet.
In generative search, every one of these assumptions breaks down:
- Dynamic Natural Language Synthesis: AI engines generate original text token by token. An engine might recommend five brands in a numbered list, compare two platforms in a descriptive table, or summarize general industry practices without naming any individual vendor.
- Probabilistic Sampling (Stochasticity): Because language models utilize temperature and top-$p$ decoding parameters, entering the exact same prompt multiple times can produce different answers, cite different web pages, or alter the order of recommendations.
- Multi-Path Attribution: An engine can mention your brand name without linking to your site, link to your site without explicitly mentioning your product, or cite a third-party review website (such as G2, Reddit, or a media publication) as the evidence source for your brand’s capabilities.
To capture meaningful data in this environment, search teams must shift from tracking static keyword positions to monitoring probabilistic visibility rates across a representative prompt corpus.
The 5-Stage AI Visibility Measurement Framework
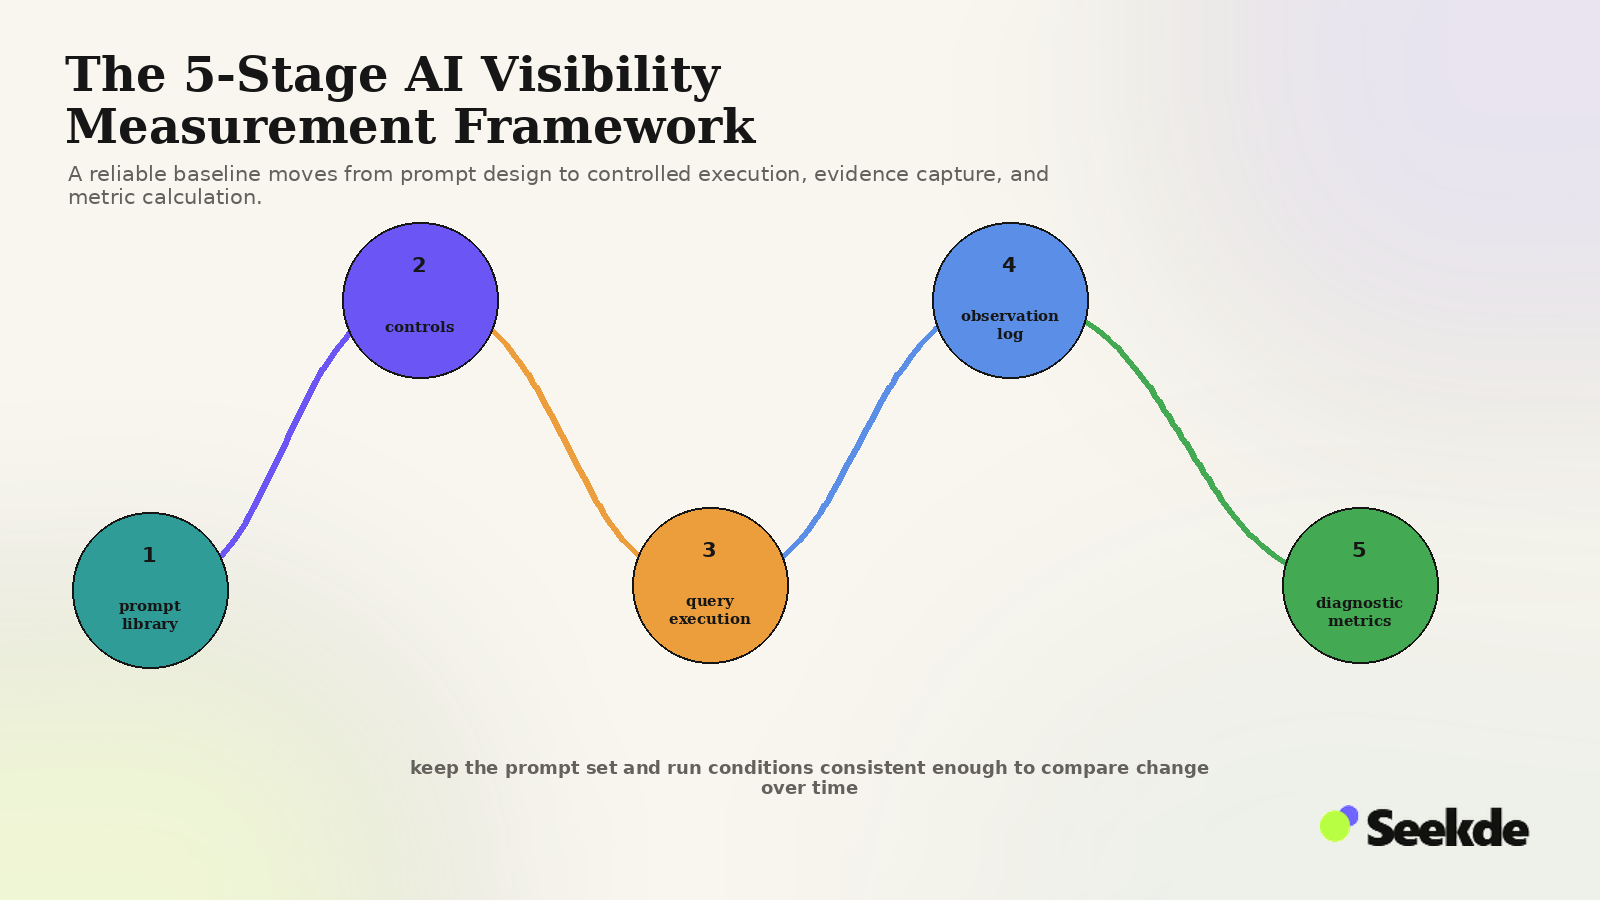
Build balanced intent clusters
Clean sessions & geo-baselines
Test major generative engines
Record mentions, links, sources
Derive diagnostic ratios
Stage 1: Design and Segment Your Prompt Library
Measurement begins with constructing an objective prompt set that reflects real user inquiry across the customer journey. Rather than testing only broad head terms (e.g., "accounting software"), your prompt library must incorporate natural language queries with explicit context and constraints.
Structure your library across five core intent tiers:
- Category & Definitional: General queries exploring industry concepts ("What is generative engine optimization and how does it work?").
- Evaluative & Commercial: High-intent buyer inquiries ("What are the best lightweight CRMs for a 20-person consulting firm?").
- Comparative & Shootout: Head-to-head evaluation queries ("How does Brand A compare to Brand B for automated invoicing?").
- Navigational & Brand-Specific: Inquiries directly referencing your company ("What integrations does Platform X support?").
- Operational & Troubleshooting: Post-purchase and technical implementation queries ("How to configure SSO in Platform X").
For comprehensive guidelines on prompt taxonomy and sampling size, refer to our protocol on How to Build an AI Search Prompt Monitoring Set.
Stage 2: Establish Observation Controls
Because generative models adapt to conversational context and personalized signals, testing environments must be strictly controlled to ensure reproducibility:
- Unauthenticated Sessions: Run test queries in clean browser environments (incognito/private windows) or unauthenticated API sessions to prevent personal search history, previous conversational turns, or stored user preferences from biasing results.
- Disabled Memory Features: In platforms like ChatGPT, ensure persistent personalization memory features are cleared or disabled during measurement runs.
- Geographic Consistency: Fix the geographic IP location (e.g., using dedicated residential or regional proxies) to avoid regional routing variations between tests.
- Multi-Run Sampling: Execute each prompt a minimum of three to five times per observation window to account for model temperature and output stochasticity, as documented in Why AI Visibility Rankings Change Between Runs.
Stage 3: Multi-Platform Query Execution
Do not assume that visibility on one platform translates to visibility on another. Retrieval mechanisms, grounding indices, and citation rules differ substantially across major platforms:
- Google AI Overviews: Uses Google’s core search index and retrieval systems; frequently cites high-ranking organic pages, forums, and top-tier publishers.
- Google AI Mode: Interactive conversational search emphasizing multi-turn exploration and contextual entity grounding.
- ChatGPT Search: Relies on OpenAI’s SearchBot retrieval pipelines and search partner indices, displaying inline link cards with
utm_source=chatgpt.comparameters. - Perplexity: Employs rapid query fan-out across multiple search sub-queries, displaying structured numbered citation brackets and real-time source pills.
- Microsoft Copilot: Grounded in the Bing index, integrating Copilot reference drawers with explicit IndexNow support.
A balanced audit executes the prompt library across all relevant platforms to identify engine-specific coverage gaps.
Stage 4: Record Structured Observation Data
For every prompt execution, capture standardized observation data. Do not rely on subjective impressions or casual notes. Maintain a structured ledger containing the following fields:
| Field | Description | Example Entry |
|---|---|---|
prompt_id |
Unique identifier from prompt library | PRM-COMM-042 |
prompt_text |
Exact query string submitted | "Best customer support software for Shopify stores" |
platform |
Tested search engine | ChatGPT Search |
timestamp |
UTC execution date and time | 2026-09-06T14:30:00Z |
mention_detected |
Was the brand named in the text? (Boolean) | TRUE |
citation_detected |
Was a domain link provided? (Boolean) | TRUE |
first_party_cited |
Did the citation point to the official site? | FALSE |
cited_urls |
Exact URLs hyperlinked in the response | https://www.g2.com/products/brand-x/reviews |
third_party_sources |
Outside domains supporting brand mention | G2.com, Reddit.com |
recommendation_tier |
Contextual positioning in response | Top Recommendation (Item 1 of 4) |
competitors_named |
Competing brands surfaced in the same answer | Zendesk, Gorgias, Freshdesk |
Stage 5: Compute Core Diagnostic Metrics
Once observation data is logged across your prompt set, compute the fundamental ratios defined in What Is AI Search Visibility?:
-
Brand Mention Rate:
$$text{Mention Rate (%)} = left(frac{text{Total Prompt Runs with Brand Mention}}{text{Total Valid Observed Prompt Runs}}right) times 100$$ -
Domain Citation Rate:
$$text{Citation Rate (%)} = left(frac{text{Total Prompt Runs with Domain Citation}}{text{Total Valid Observed Prompt Runs}}right) times 100$$ -
First-Party Citation Ratio:
$$text{First-Party Ratio (%)} = left(frac{text{Runs with Official Domain Citations}}{text{Total Runs with Brand Mention}}right) times 100$$ -
Relative Share of Voice (SOV):
Compare your brand’s mention count against total tracked competitor mentions across the prompt set, following the methodology in What Is AI Share of Voice?.
The Strategic Diagnostic Matrix: How to Interpret Audit Findings
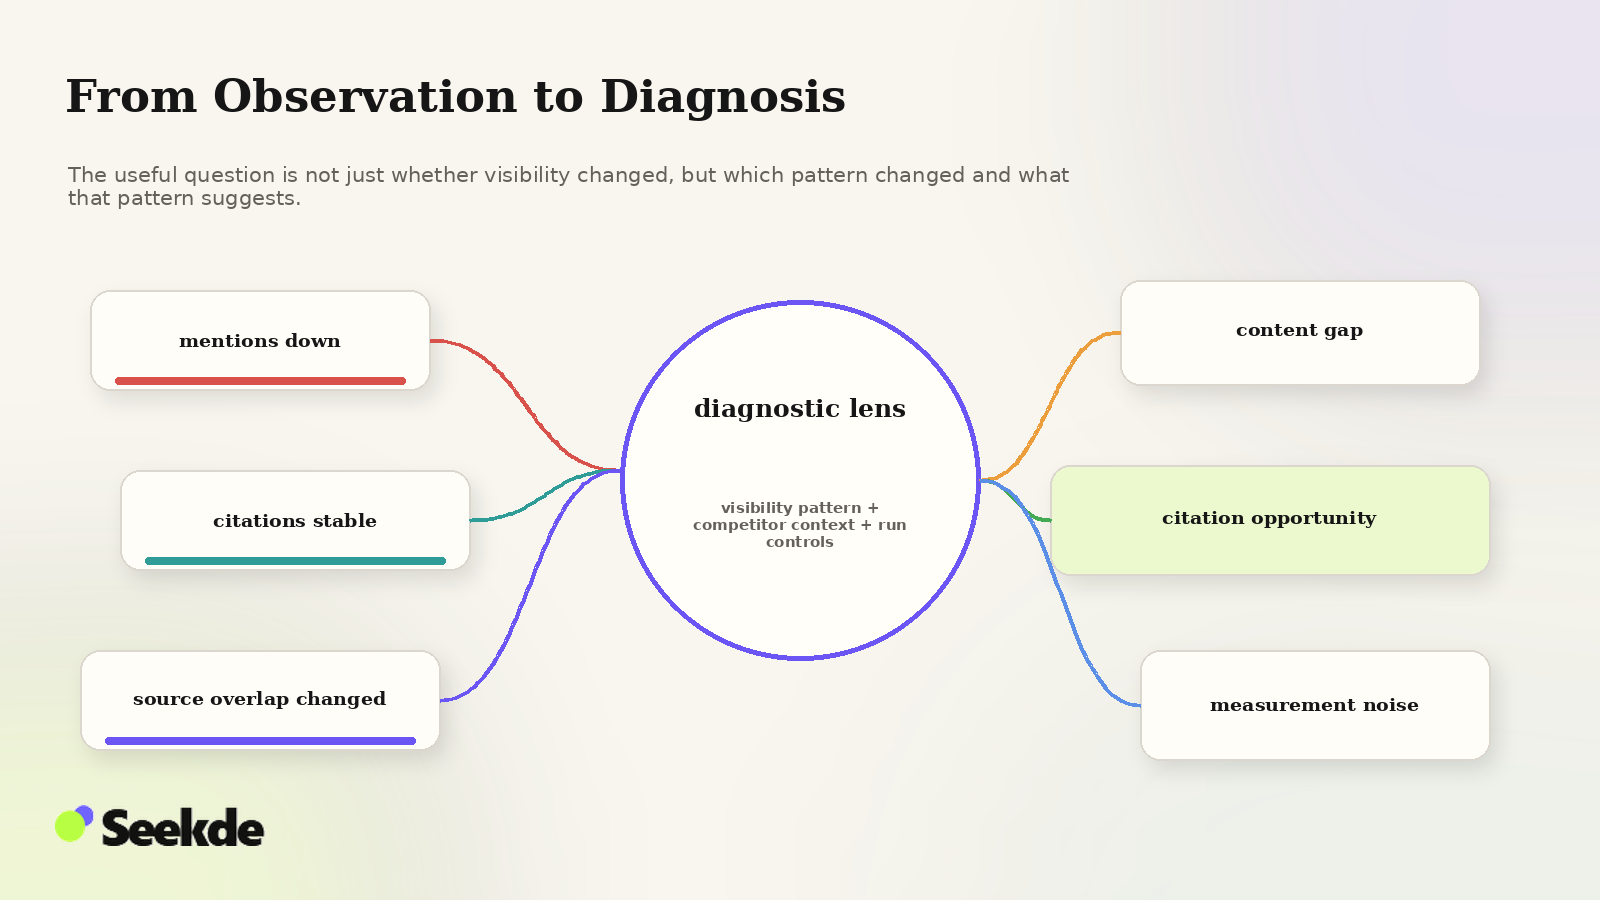
Raw metrics become useful only when paired with qualitative diagnosis. Analyzing the relationship between mentions and citations reveals where marketing and technical optimization efforts should focus:
High Citations, High Mentions
Authority Position: Maximum generative footprint with verified domain links.
High Citations, Low Mentions
Niche Citation Specialist: Referenced for specific technical facts, but low brand presence.
Low Citations, Low Mentions
Invisible Entity: Outside model memory and ignored during RAG retrieval passes.
Low Citations, High Mentions
Attribution Leakage: AI synthesizes brand claims without linking back to source domain.
Quadrant 1: High Mentions, High Citations (Optimal Presence)
- Signal: The brand is frequently recommended in the generated prose, and the engine links directly to your first-party domain as supporting proof.
- Action: Monitor stability across model updates. Expand coverage into adjacent informational and comparative prompt clusters.
Quadrant 2: High Mentions, Low Citations (The Authority Deficit)
- Signal: The engine recommends your product, but cites third-party reviews, software directories, or Reddit discussions rather than your website.
- Action: Optimize on-page content architecture. Implement clear, extractable technical specifications, structured pricing data, and concise self-contained answers that neural rerankers can extract directly from your domain, as examined in AI Citations vs Brand Mentions.
Quadrant 3: Low Mentions, High Citations (The Uncredited Reference)
- Signal: The engine cites your original research, statistics, or documentation as evidence, but fails to mention your commercial product as a solution in the synthesized text.
- Action: Build direct semantic bridges between informational assets and product solutions. Connect research studies to commercial use cases and reinforce brand entity associations in schema markup.
Quadrant 4: Low Mentions, Low Citations (Total Discovery Absence)
- Signal: The brand does not appear in synthesized answers or source lists for relevant category queries.
- Action: Conduct a comprehensive technical crawl audit to ensure AI bots are not blocked by robots.txt rules (AI Crawlers Explained, Robots.txt Configuration). Strengthen digital PR and co-occurrence across authoritative trade publications to seed the model’s retrieval pool.
Manual Auditing vs. Automated Tooling: Choosing the Right Approach
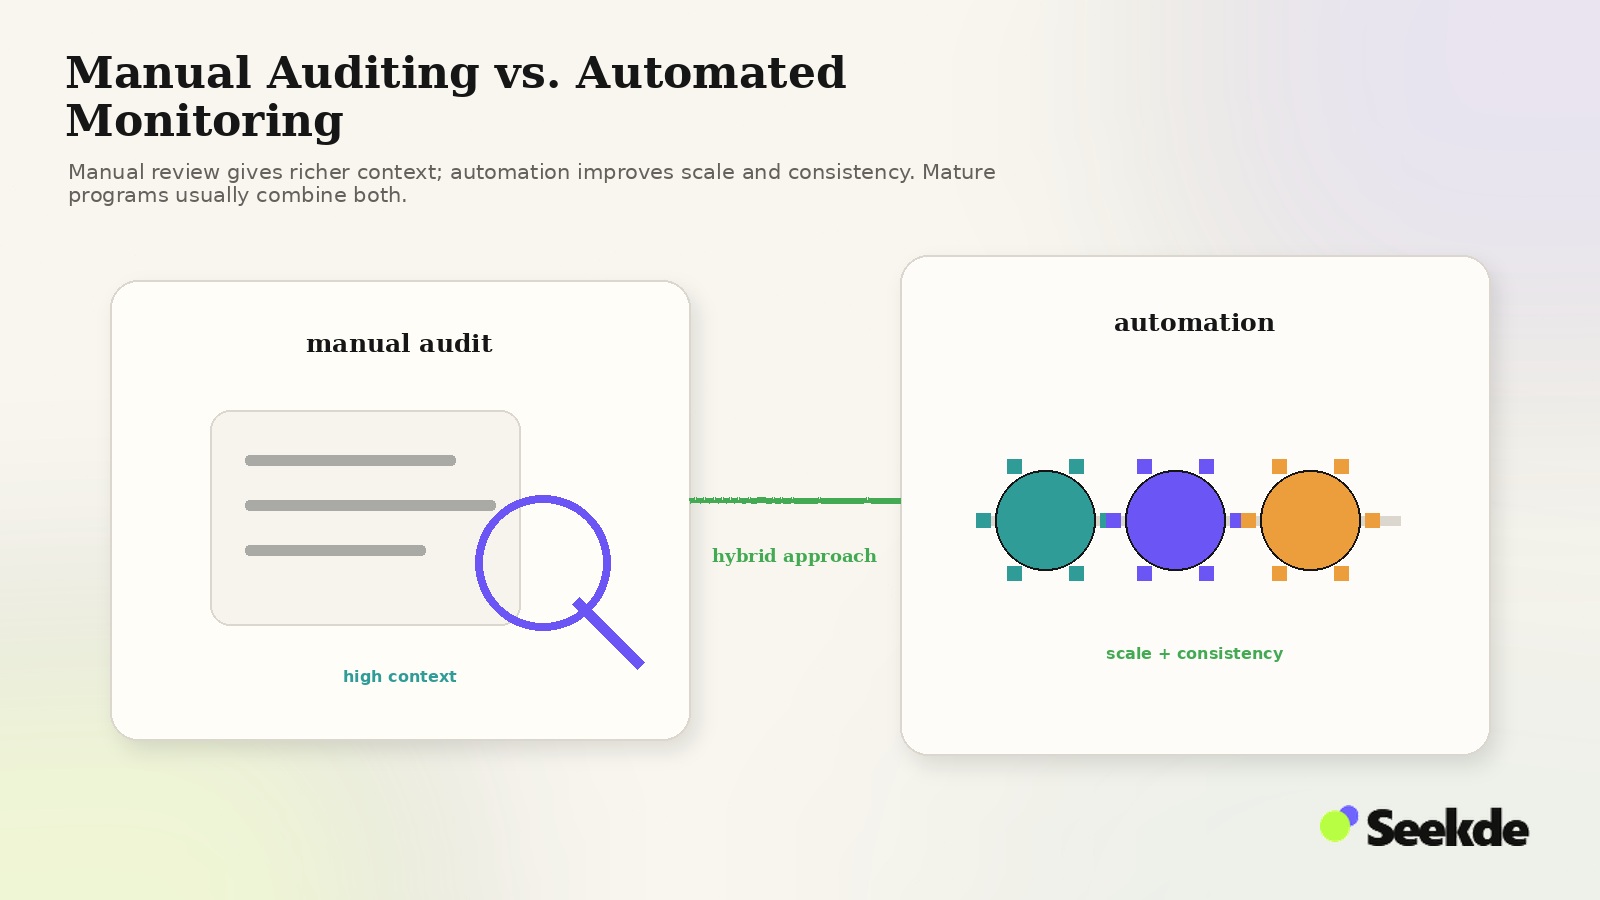
Organizations must balance accuracy, cost, and scale when establishing an AI search measurement cadence.
| Dimension | Manual Auditing Protocol | Automated Scraping / API Tools |
|---|---|---|
| Observation Fidelity | High; captures true user-facing DOM, hover cards, interactive carousels, and layout context. | Variable; headless browsers often encounter CAPTCHAs, bot blocks, or simplified fallback layouts. |
| Scale & Frequency | Limited; labor-intensive, suitable for 50–150 core high-value commercial prompts monthly. | High; can query thousands of prompt variations across multiple engines daily. |
| API vs. UI Discrepancy | Zero discrepancy; tests the exact web interface encountered by real searchers. | Significant risk; model APIs lack the proprietary search pipelines and UI citation layers of commercial web search products. |
| Cost | Internal team time. | Subscription software costs, proxy infrastructure, or per-query API fees. |
Recommended Hybrid Methodology:
For most enterprises, the most effective approach combines automated weekly tracking of a broad prompt library (to detect high-level trend shifts and sudden drops) with monthly, manual forensic audits of high-priority commercial prompts to verify citation integrity, sentiment accuracy, and competitor positioning.
Closing the Loop: Connecting Search Presence to Web Analytics
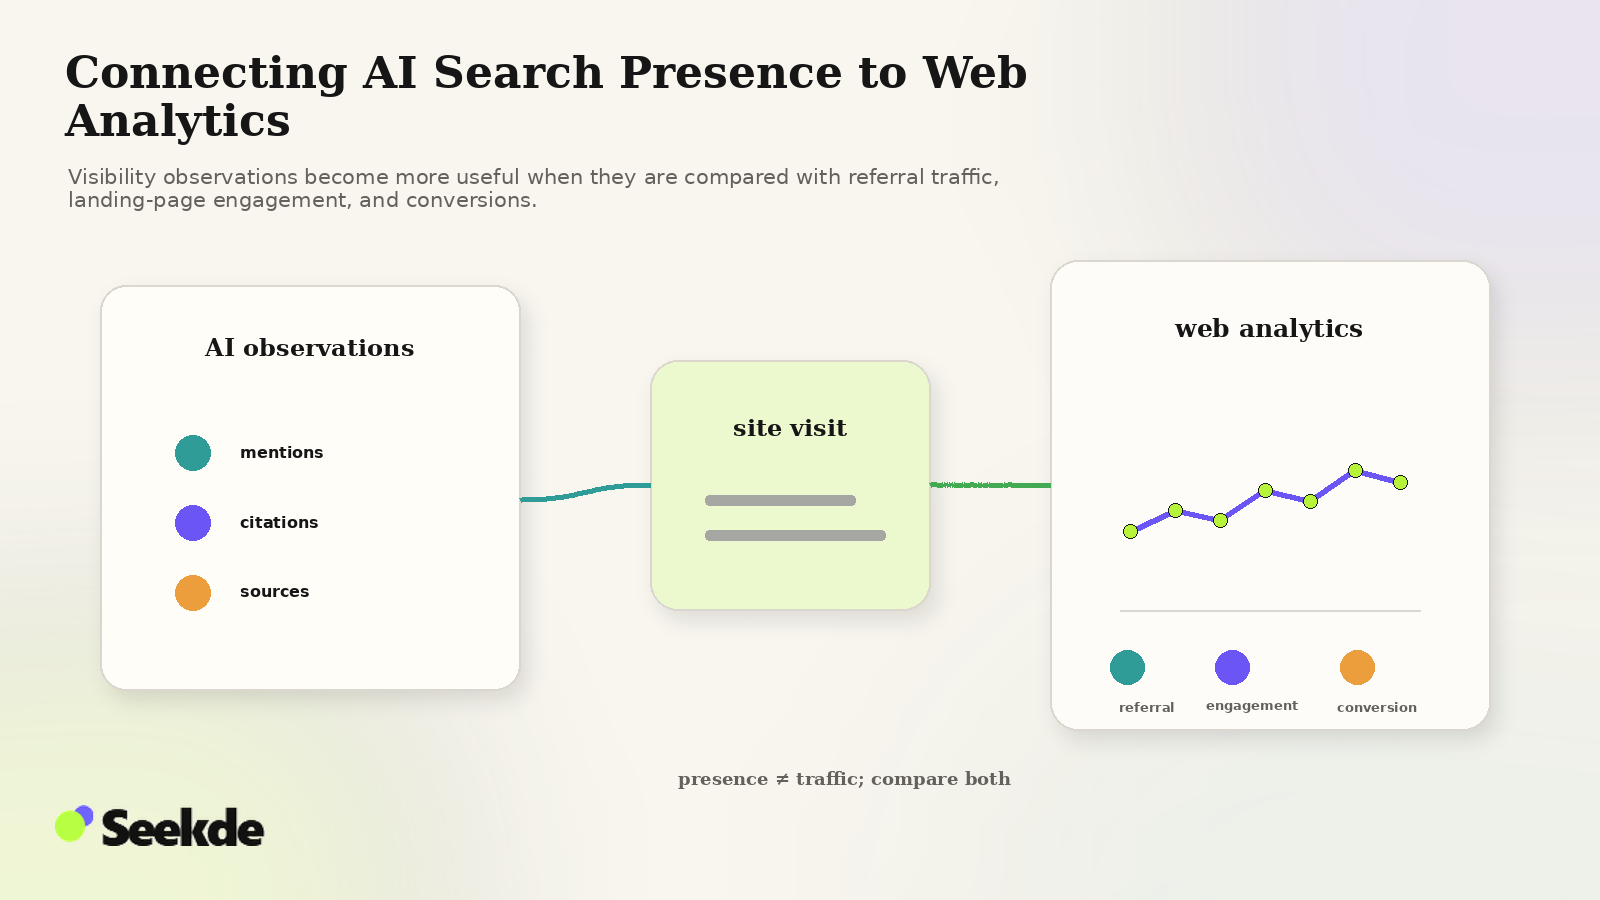
Monitoring AI search visibility on the engine side is only half the equation. To justify investment, search teams must connect off-site visibility to on-site business outcomes.
- Verify Outbound Traffic in GA4: Configure custom channel groupings to isolate referral traffic originating from generative engines, tracking sessions where
utm_source=chatgpt.comor referrers matchperplexity.aiandcopilot.microsoft.com. Follow the step-by-step setup in How to Track ChatGPT Referral Traffic in GA4. - Analyze Google Search Console Generative Performance: Utilize Search Console’s dedicated Generative AI report (launched August 31, 2026) to track verified generative impressions across AI Overviews and AI Mode (with clicks and position metrics captured in broader Search Performance), as detailed in How to Track AI Search Visibility in Google Search Console.
- Measure Downstream Conversions: Track whether visitors originating from generative search citations demonstrate higher engagement rates, longer session durations, and higher assisted conversion rates compared to traditional organic search visitors.
Practical Implementation Checklist for Search Teams
To launch an initial AI search visibility measurement workflow:
- [ ] Define 50 Core Prompts: Assemble an initial prompt library covering category, commercial, comparative, and navigational intents.
- [ ] Select Target Platforms: Identify which engines matter most to your target audience (e.g., Google AI Overviews and ChatGPT for B2B; Perplexity and Copilot for technical professionals).
- [ ] Establish Clean Testing Profiles: Create dedicated, unauthenticated browser profiles with fixed geographic parameters and cleared session memory.
- [ ] Execute Baseline Audit: Run three iterations of each prompt across target engines, logging mentions, citations, source URLs, and competitor presences in your observation schema.
- [ ] Calculate Baseline Ratios: Compute initial Mention Rate, Citation Rate, and First-Party Citation Ratio.
- [ ] Identify Attribution Gaps: Classify your performance against the Strategic Diagnostic Matrix to prioritize technical, content, or PR remediation.
- [ ] Schedule Recurring Tracking: Re-audit the core prompt set on a bi-weekly or monthly cadence to monitor longitudinal trends and model updates.