Refreshing existing content for AI search is the systematic process of retrofitting legacy blog posts and documentation to meet the structural, propositional, and technical standards required by generative retrieval engines. Most existing enterprise content libraries were produced during the conventional SEO era, when ranking formulas prioritized high total word counts, repeated keyword variants, lengthy introductory hooks, and broad topical surveys. In a generative search ecosystem powered by Google AI Overviews, Perplexity, ChatGPT Search, and Microsoft Copilot, these legacy patterns act as active impediments to discoverability.
When conversational answer engines evaluate legacy articles, retrieval chunkers frequently encounter hundreds of words of introductory fluff before finding a direct answer. Unanchored relative dates ("over the past few years"), missing schema markup, unformatted narrative tables, and ambiguous pronoun chains prevent neural cross-encoders from selecting your passages as authoritative grounding sources.
Rather than deleting older content or writing entirely new archives from scratch, publishers can execute a structured Content Modernization Workflow to upgrade existing high-performing URLs into dense, citation-worthy assets.
Why Legacy SEO Content Fails in Generative Search
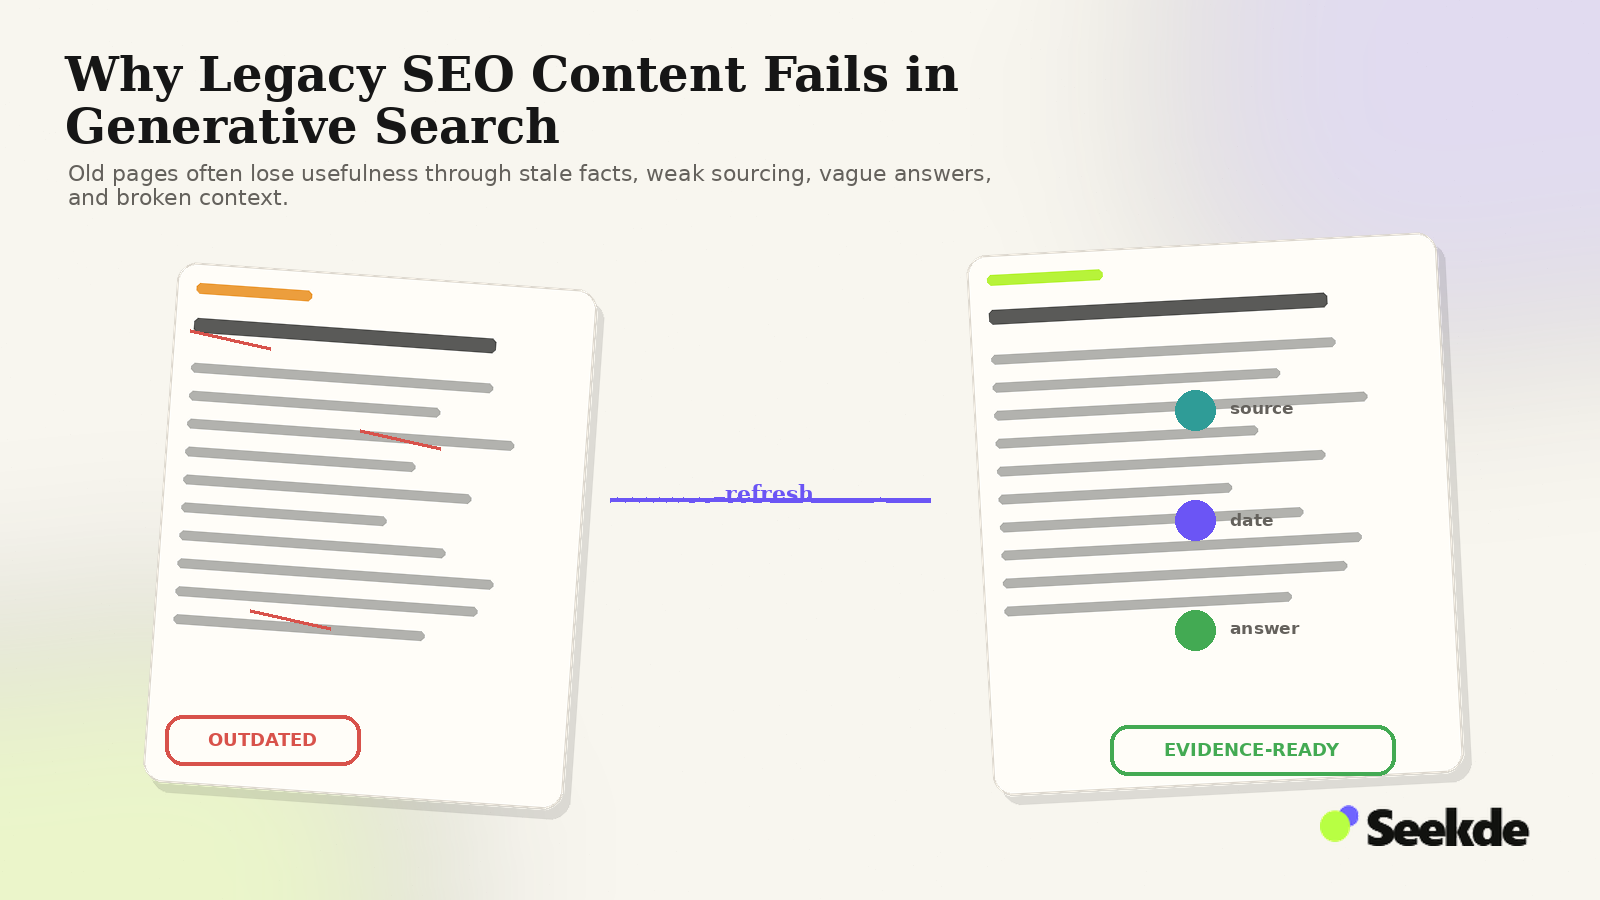
To understand how to retrofit an article, editorial teams must recognize the architectural differences between how traditional search spiders and modern RAG pipelines evaluate web pages:
RAG Failure Mode: Token Waste — Context window consumed before core answer is reached.
RAG Failure Mode: Context Loss — Neural chunkers cannot associate passage with user intent.
RAG Failure Mode: Chunk Demotion — Cross-encoders score passage below direct competitor answers.
RAG Failure Mode: Entity Absence — Knowledge graph fails to resolve named entity attributes.
| Legacy SEO Pattern | Why It Succeeded in 2018–2022 | Why It Fails in Modern AI Search |
|---|---|---|
| Throat-Clearing Introductions | Maximized initial word count and provided opportunities to weave in long-tail keyword variations. | Consumes vector context window budgets without delivering extractable factual propositions; downweighted by neural rerankers. |
| Delayed Direct Answers | Forced visitors to scroll down the page, artificially inflating on-page dwell time and session duration. | Chunkers slice documents into 200–500 token blocks; if the opening chunk lacks the answer, the engine retrieves a competitor’s concise summary. |
| Narrative Bullet Points | Easy for human readers to scan; provided simple visual whitespace. | Lacks relational entity-attribute bindings; semantic HTML <table> elements are vastly preferred for multi-variable synthesis. |
| Unanchored Relative Dates | Allowed articles to appear "evergreen" without manual updating ("recently", "in modern times"). | Introduces temporal desynchronization and hallucination risk; models favor explicitly dated evidence and recent ISO timestamps. |
| Missing / Minimal Schema | Search engines could infer page topics through standard lexical parsing and meta descriptions. | Deprives generative models of machine-readable entity bridges (sameAs, author, publisher, knowsAbout). |
The Seekde 4-Stage Content Modernization Workflow
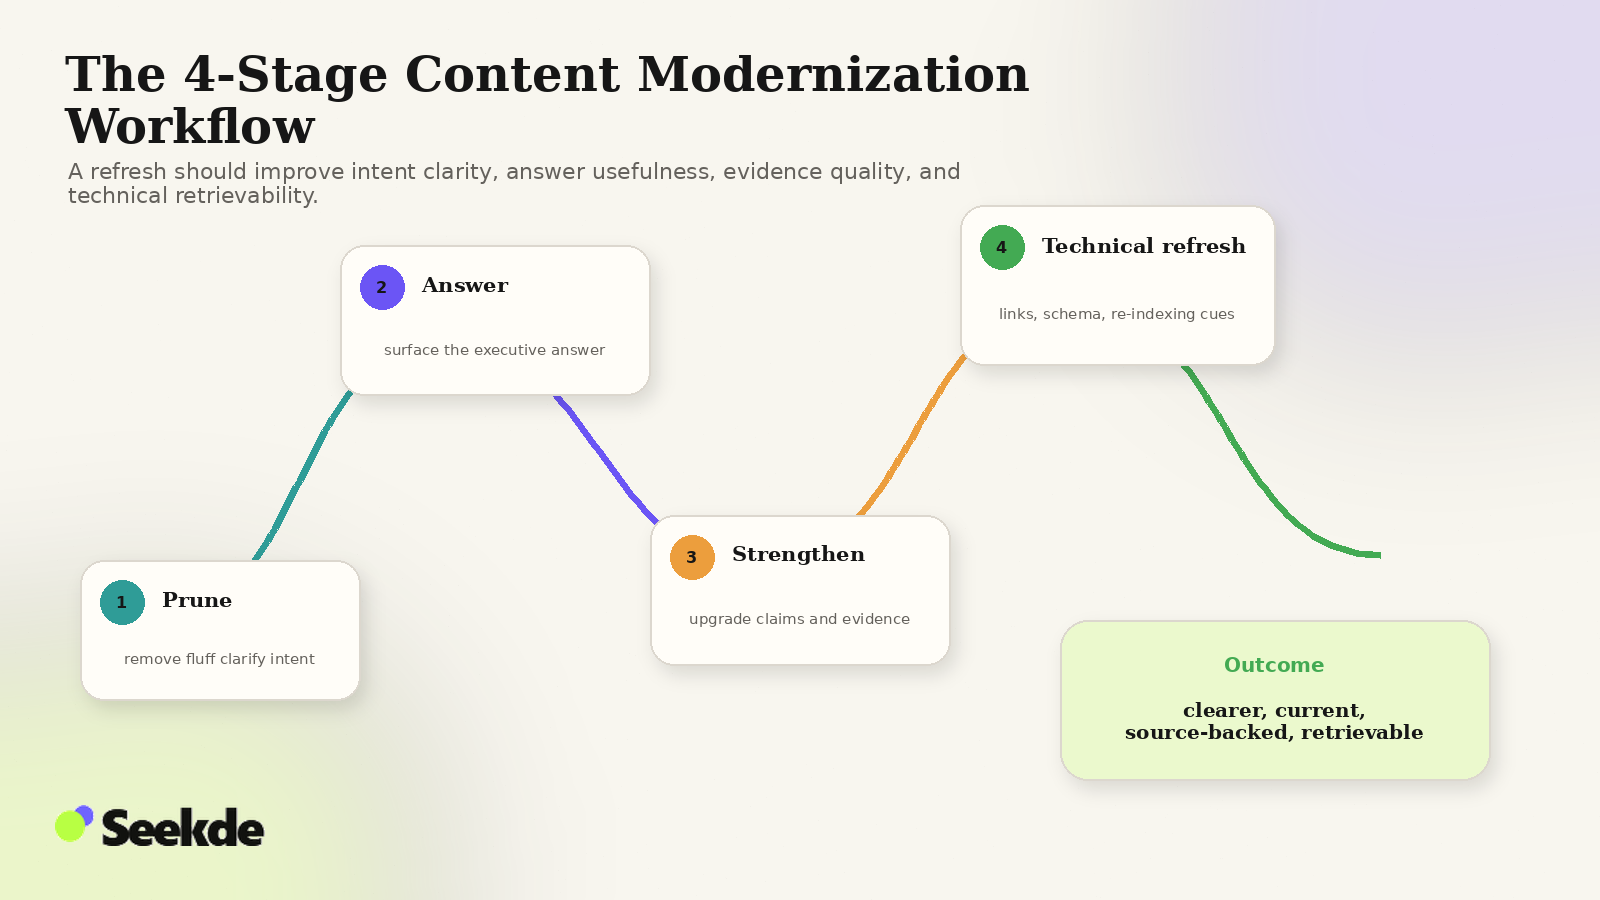
Seekde has codified a repeatable, four-stage protocol for transforming legacy articles into high-performing generative citation targets:
Stage 1: Prune Fluffy Text and Isolate Primary Intent
Begin by auditing the article’s existing structure. Strip away all generic throat-clearing prose:
- Delete introductory paragraphs starting with "In today’s fast-paced digital world…" or "Content marketing has evolved dramatically over the years…".
- Isolate the single primary question or procedural task the article satisfies. If an old 4,000-word post attempts to answer six unrelated questions, split the article into dedicated, focused spoke URLs.
- Replace generic subheadings ("Background", "Details", "Looking Forward") with descriptive, entity-rich headings ("How Token Limits Constrain Passage Retrieval").
Stage 2: Inject the Executive Answer Block (The TL;DR Anchor)
Rewrite the opening section to deliver the definitive answer within the first 60 words:
- Bolded Direct Answer: State the definition, solution, or core finding immediately beneath the primary
<h1>. - Contextual Expansion: Follow the direct answer with a 2-to-3 sentence paragraph outlining key qualifications, methodologies, or operational boundaries.
- Stand-Alone Clarity: Ensure that if this opening block is extracted as an isolated snippet, it provides complete semantic meaning without referencing subsequent sections.
Example Before (Legacy):
"When managing a modern website, technical SEO is one of the most important things you can invest in. Over the years, many people have asked whether they should use robots.txt to control artificial intelligence. In this guide, we will explore the history of robots.txt and help you decide what to do…"
Example After (Modernized for AI):
To prevent AI search engines from scraping content for foundation model training while preserving conversational citation visibility, website administrators must configure distinct robots.txt rules under RFC 9309 standards. Allowing OAI-SearchBot while disallowing GPTBot permits real-time search discovery while opting out of offline model training.
Stage 3: Upgrade Claims to the CES Standard and Convert Lists to Tables
Audit every factual claim, metric, and comparative feature in the body text:
- Apply the Claim-Evidence-Source (CES) Matrix: Replace vague assertions ("most enterprise tools cost a lot of money") with quantified Tier 1 statements ("Enterprise visibility platforms start at $1,500 to $4,500 per month as of Q1 2026, according to published vendor tier sheets").
- Convert Narrative Comparisons into HTML Tables: Locate narrative bullet points that compare software tools, crawler permissions, or algorithmic metrics. Re-architect them into semantic
<table>elements with explicit column headers (<th>). - Anchor Dates: Replace all instances of "currently", "recently", and "last year" with exact calendar dates or quarter markers.
Stage 4: Implement Technical Schema and Re-Indexing Protocols
Ensure the page’s technical infrastructure supports machine extraction:
- Validate Canonical Tags: Confirm that the URL features an absolute, self-referencing canonical tag to avoid splitting retrieval signals across tracking parameters.
- Inject Complete JSON-LD Schema: Upgrade basic
Articleschema toTechArticleor addFAQPage(for informational procedures) incorporatingauthor,publisher, andsameAsentity links (as detailed in our schema markup for AI search guide). - Trigger Search Engine Recrawling: Submit the updated URL via Google Search Console and Bing Webmaster Tools. If significant factual changes were made, monitor server access logs to confirm visits from
GooglebotandOAI-SearchBot.
(Editorial Integrity Rule: Never manipulate the publication or modification timestamp simply to simulate freshness without making substantive factual updates. Generative retrieval engines and search indexers evaluate document revision histories; updating timestamps without corresponding changes to facts, data, or structure risks algorithmic demotion for deceptive freshness practices.)
Retrofit Case Study: Transforming a Legacy Explainer
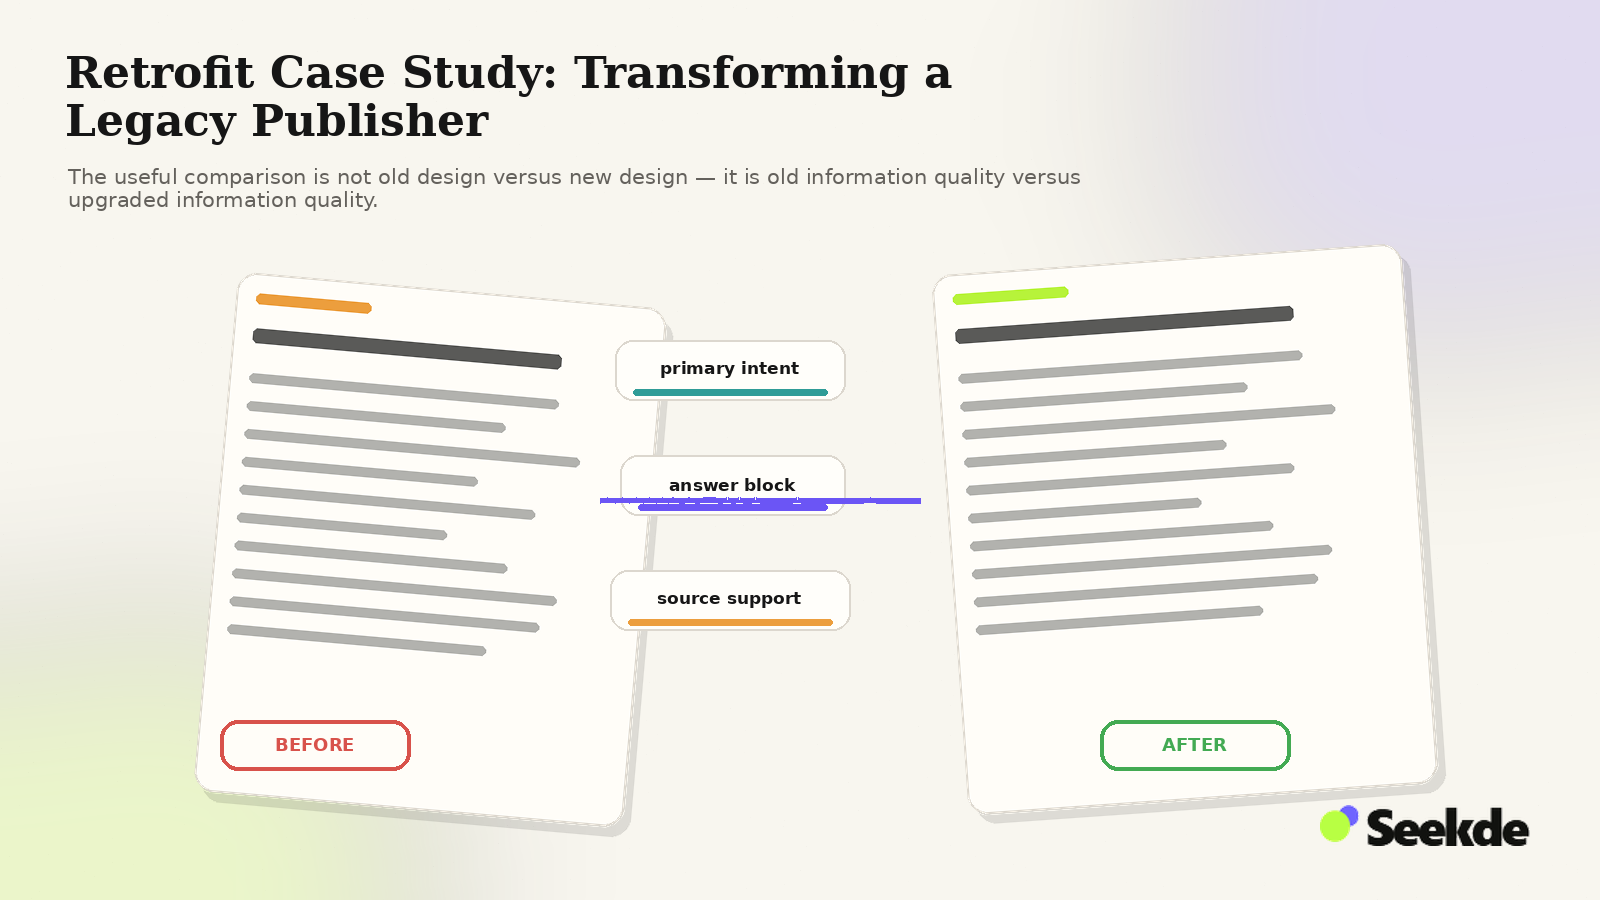
To see the workflow in action, review this teardown of a real-world article retrofit:
Legacy Version (Pre-Modernization)
- Title: The Ultimate Guide to Schema Markup
- Word Count: 2,800 words
- Structure: 600 words of history before explaining JSON-LD; no tables; code embedded in screenshot images; no dates on recommendations; generic author bio ("Admin").
- Generative Performance: 0 citations across Google AI Overviews and Perplexity; high bounce rate from human readers.
Modernized Version (Post-Modernization)
- Title: Schema Markup for AI Search: What Actually Matters
- Word Count: 2,240 words (pruned 560 words of historical fluff).
- Structure:
- Immediate 50-word bold answer block defining schema’s role in RAG entity disambiguation.
- Semantic HTML table comparing supported schema types (
Organization,Article,TechArticle) vs. deprecated types (FAQPagefor non-authoritative sites). - Code snippets migrated into
<pre><code class="language-json">syntax blocks. - Statistics updated with exact dates and primary documentation links to Google Search Central.
- Author profile upgraded with
Personschema and verified LinkedInsameAslinks.
- Generative Performance: Verified inclusion as a primary grounding source in conversational answer engines for prompts regarding "best schema types for generative search".
The Triage Prioritization Matrix: Which Legacy Articles to Refresh First
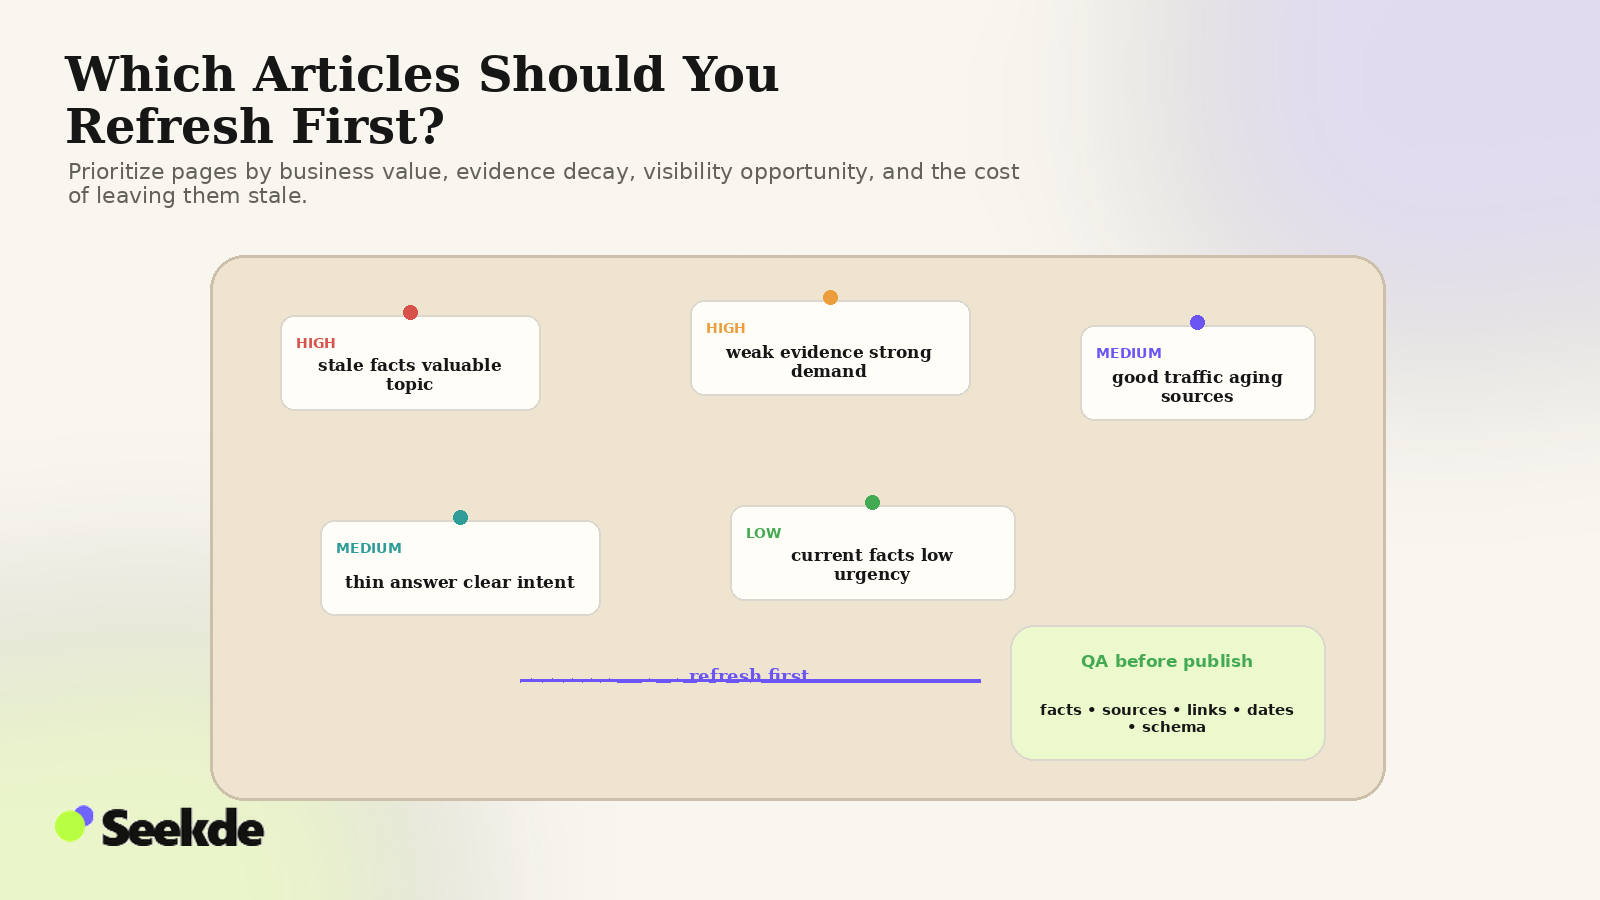
Not every legacy article warrants an immediate rewrite. Prioritize your content catalog using this 4-quadrant triage framework:
High vs Low Existing Organic Impressions / Traffic
Citation Optimization (High Impressions / Established Authority)
- High organic traffic & established domain authority
- Action: Inject Inverted-Pyramid Answer Blocks & Data Tables
- Outcome: Immediate citation card capture in AI Overviews
Urgent Modernization (High Impressions / Zero Citations)
- High search impression exposure but zero generative citations
- Action: Full 4-Stage Retrofit (Disclose answers, prune fluff)
- Outcome: Reverse zero-click traffic decay
Technical Refresh (Moderate Traffic / Outdated Data)
- Moderate traffic with outdated facts and broken links
- Action: Update Statistics, Methodology Dates & Recrawl
- Outcome: Maintain crawler freshness and entity authority
Retire or Consolidate (Low Traffic / Thin Content)
- Low organic traffic with zero generative impressions
- Action: 301 Redirect to Pillar Hubs or Prune Archive
- Outcome: Conserve crawler budget for high-intent articles
- Quadrant 1 (High Traffic, High Authority): These pages already enjoy strong crawling frequency and backlink equity. Adding an executive answer block and semantic comparison tables immediately converts them into generative citation targets.
- Quadrant 2 (High Impressions, Zero AI Inclusion): Pages that rank on page one of traditional SERPs but are omitted from AI Overviews suffer from structural or density flaws. These are your highest-ROI modernization candidates.
The Content Refresh Quality Assurance Checklist
Use this 10-point audit checklist before marking a refreshed article complete:
- [ ] 1. Fluff Elimination: Were all generic, throat-clearing introductory paragraphs removed?
- [ ] 2. Immediate Direct Answer: Does a bolded, standalone summary answer appear in the first 60 words?
- [ ] 3. Entity-Dense Headings: Do all
<h2>and<h3>tags explicitly name the subject, process, or technology? - [ ] 4. Standalone Chunk Cohesion: Can subsections be extracted without losing semantic meaning?
- [ ] 5. Tabular Conversions: Were all narrative comparisons converted into native HTML
<table>elements? - [ ] 6. CES Evidence Compliance: Are claims backed by specific numbers, sample sizes, and primary documentation links?
- [ ] 7. Temporal Anchoring: Were all relative time references ("recently", "last month") replaced with specific calendar dates?
- [ ] 8. Clean Code Delimitation: Are technical snippets enclosed in language-tagged
<pre><code>blocks? - [ ] 9. Structured Schema Integration: Was valid JSON-LD schema markup implemented with complete author and publisher attributes?
- [ ] 10. Single Theme H1 Integrity: Does the article body contain zero
<h1>tags, preserving clean document hierarchy?
Summary: Maximizing the Value of Your Existing Content Library
Your existing content library is one of your organization’s most valuable assets in the transition to generative search. The goal is not to abandon the research, expertise, and authority you have built over years, but to repackage that authority in the structural language that AI search systems consume.
By eliminating narrative fluff, front-loading direct answers, structuring comparative data in semantic tables, and verifying all statistics with primary links, you transform legacy blog posts into powerful, resilient citation engines.
Executing a disciplined modernization workflow ensures that your entire historical catalog continues to generate brand visibility, referral traffic, and industry authority across the AI search landscape.
Related Guides and Technical Frameworks
- How to Create Content AI Search Engines Can Cite
- What Makes a Web Page Citation-Worthy?
- How to Structure Articles for AI Search
- Do Statistics and Sources Improve AI Citations?
- Schema Markup for AI Search: What Actually Matters
- Entity SEO for AI Search: A Practical Guide
- How AI Search Engines Find, Retrieve and Cite Web Content