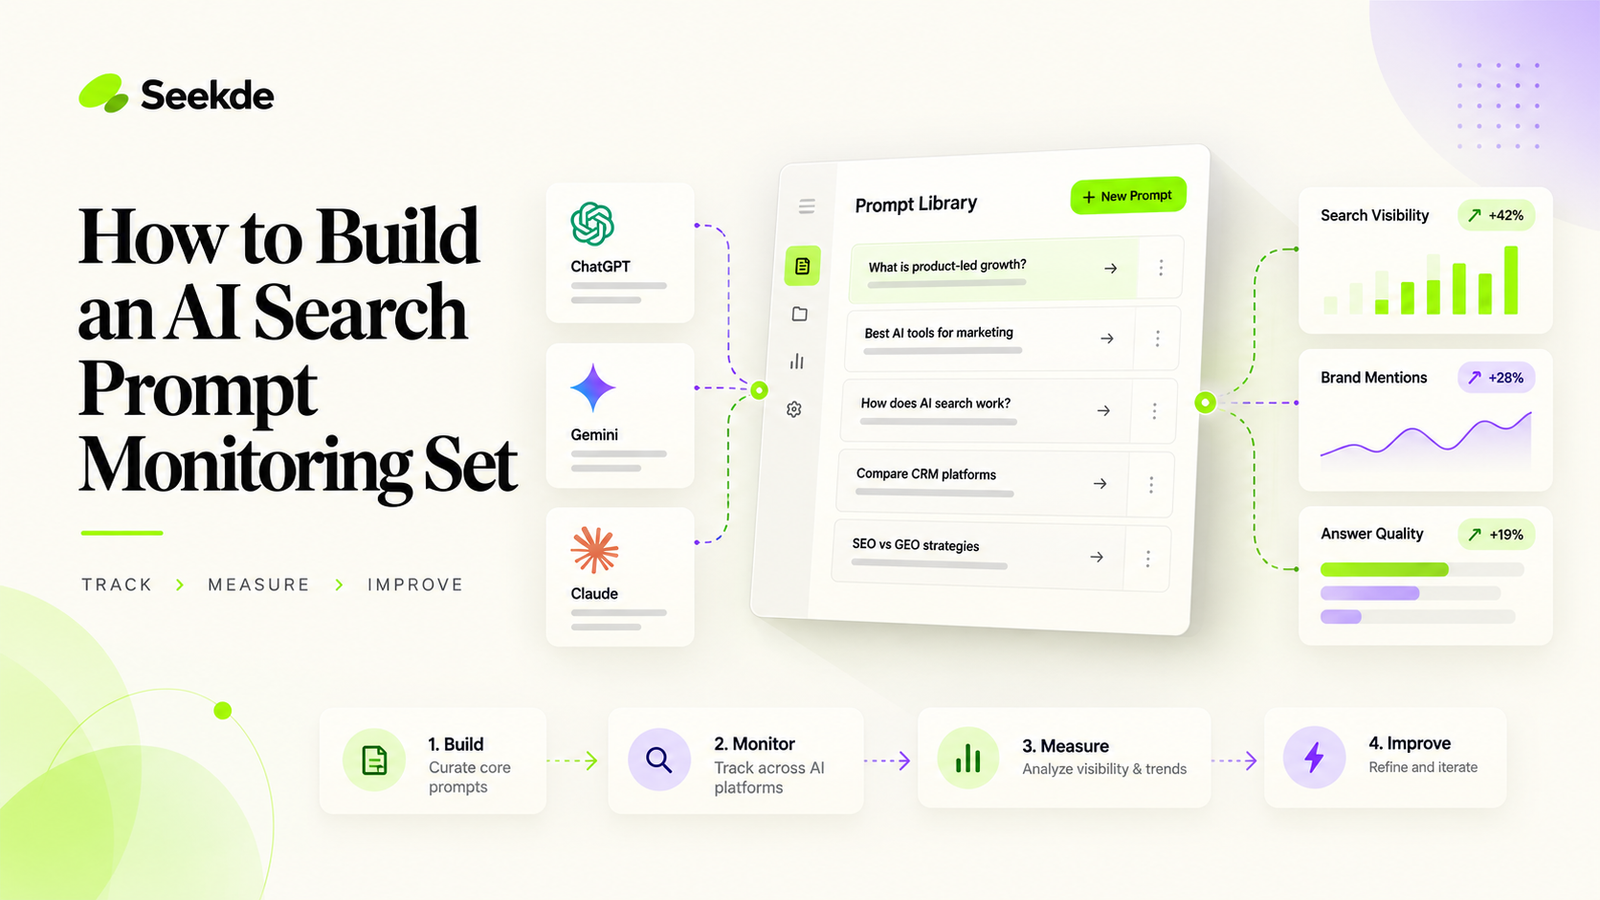
An AI search prompt monitoring set is a structured, representative library of natural language queries used to systematically evaluate an entity’s visibility, citations, and competitive positioning across generative answer engines.
In traditional SEO, visibility auditing begins with a target keyword list. In generative search, however, users rarely interact through two-word keyword fragments. They query platforms like ChatGPT Search, Perplexity, Google AI Overviews, and Microsoft Copilot using complete, conversational sentences embedded with specific operational constraints, organizational context, and comparative qualifiers.
If an organization audits its AI visibility using only generic head terms, the resulting data will be dangerously unrepresentative. Building a rigorous prompt monitoring set calls for a disciplined intent taxonomy, deliberate constraint injection, syntactic variation, and strict version control.
Why Traditional Keyword Lists Fail in Generative Search
Attempting to monitor AI search presence by inputting raw SEO keywords into generative models produces misleading results for three technical reasons:
- Failure to Trigger Conversational Retrieval: A two-word keyword like "cloud security" often triggers basic definitional summaries or standard organic SERP links. A real user prompt—such as "What cloud security platforms provide automated SOC 2 compliance for AWS-native startups?"—activates complex query fan-out, multi-step web retrieval, and specialized vendor evaluation.
- Loss of Constraint Context: Language models excel at matching nuanced constraints (e.g., budget limits, technical tech stacks, team sizes, integration requirements). When constraints are omitted from test queries, models default to generic industry incumbents, completely masking your brand’s performance in its specific target niches.
- Syntactic Fragility: Because generative models are non-deterministic and sensitive to phrasing nuances (as detailed in Why AI Visibility Rankings Change Between Runs), monitoring a single keyword phrasing fails to capture the true probability distribution of your brand’s discovery.
The Five-Tier AI Search Intent Taxonomy
A representative prompt monitoring set must mirror the entire buyer journey. Seekde establishes a five-tier taxonomy that balances high-level category authority with commercial evaluation and post-purchase support:
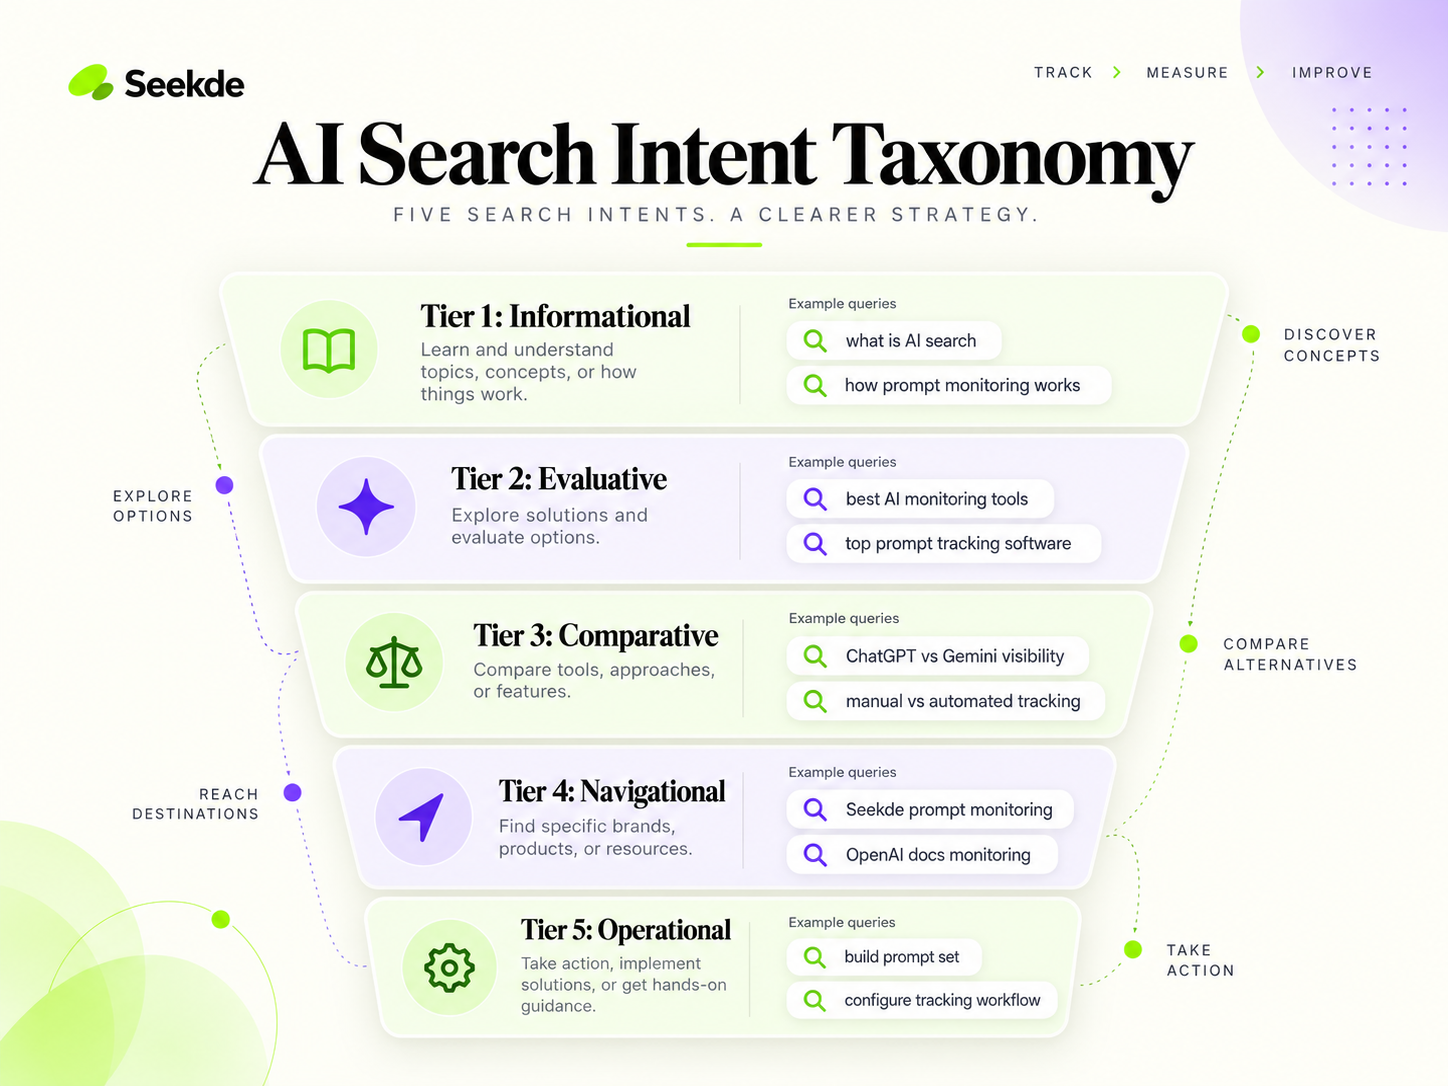
Tier 1: Category & Informational Inquiries (Top of Funnel)
- Objective: Determine whether your brand’s original research, technical guides, or frameworks are cited as foundational industry authority.
- Query Characteristics: Conceptual definitions, architectural workflows, and industry standards without explicit commercial intent.
- Example Prompts:
- "How does retrieval-augmented generation handle multi-document citation synthesis?"
- "What are the primary differences between zero-trust network access and traditional VPNs?"
- "What is the standard methodology for calculating generative search share of voice?"
- Primary Signal: First-party informational citation rate in source carousels and reference drawers.
Tier 2: Evaluative & Commercial Inquiries (Middle / Bottom of Funnel)
- Objective: Measure how frequently your product is recommended when a qualified buyer actively seeks vendor recommendations.
- Query Characteristics: Explicit persona constraints, team sizing, use cases, and budget parameters.
- Example Prompts:
- "What are the best customer support platforms for mid-sized Shopify Plus merchants?"
- "Top lightweight project management tools for 15-person remote software agencies."
- "Which enterprise data loss prevention software integrates natively with Google Workspace and Slack?"
- Primary Signal: Unweighted Brand Mention Rate and recommendation tier (primary recommendation vs secondary alternative).
Tier 3: Comparative Shootouts & Alternative Inquiries
- Objective: Track how the engine frames your capabilities, advantages, and trade-offs when evaluated directly against key competitors.
- Query Characteristics: Direct brand pairings, feature matrix queries, and migration inquiries.
- Example Prompts:
- "Platform A vs Platform B: which has better API documentation and webhook reliability?"
- "What are the top open-source alternatives to [Incumbent Brand] for self-hosted analytics?"
- "Why do companies switch from [Competitor X] to [Your Brand]?"
- Primary Signal: Comparative sentiment balance, feature accuracy, and third-party citation pathways (e.g., G2, Reddit, official comparisons).
Tier 4: Navigational & Entity Inquiries (Brand-Direct Auditing)
- Objective: Audit the factual integrity, hallucination frequency, and sentiment accuracy of answers generated specifically about your company.
- Query Characteristics: Direct queries focusing on your pricing, security compliance, architecture, and executive leadership.
- Example Prompts:
- "How much does [Brand Name] cost per seat, and is there a free trial?"
- "Does [Brand Name] support HIPAA and SOC 2 Type II compliance?"
- "What are the most common complaints or limitations reported by users of [Brand Name]?"
- Primary Signal: Factual alignment with official documentation versus synthetic hallucination of deprecated features.
Tier 5: Operational & Implementation Inquiries (Post-Purchase Support)
- Objective: Evaluate whether your technical documentation, knowledge base articles, and API references are successfully retrieved to solve technical issues.
- Query Characteristics: Procedural, error-resolution, and integration queries.
- Example Prompts:
- "How to configure SAML SSO in [Brand Name] using Okta"
- "How to resolve rate limit 429 errors when exporting data from [Brand Name] API"
- Primary Signal: First-party documentation citation dominance over unvetted community forum answers.
Core Principles of Prompt Set Construction
To prevent observer bias from invalidating audit results, search teams must adhere to four prompt engineering standards:
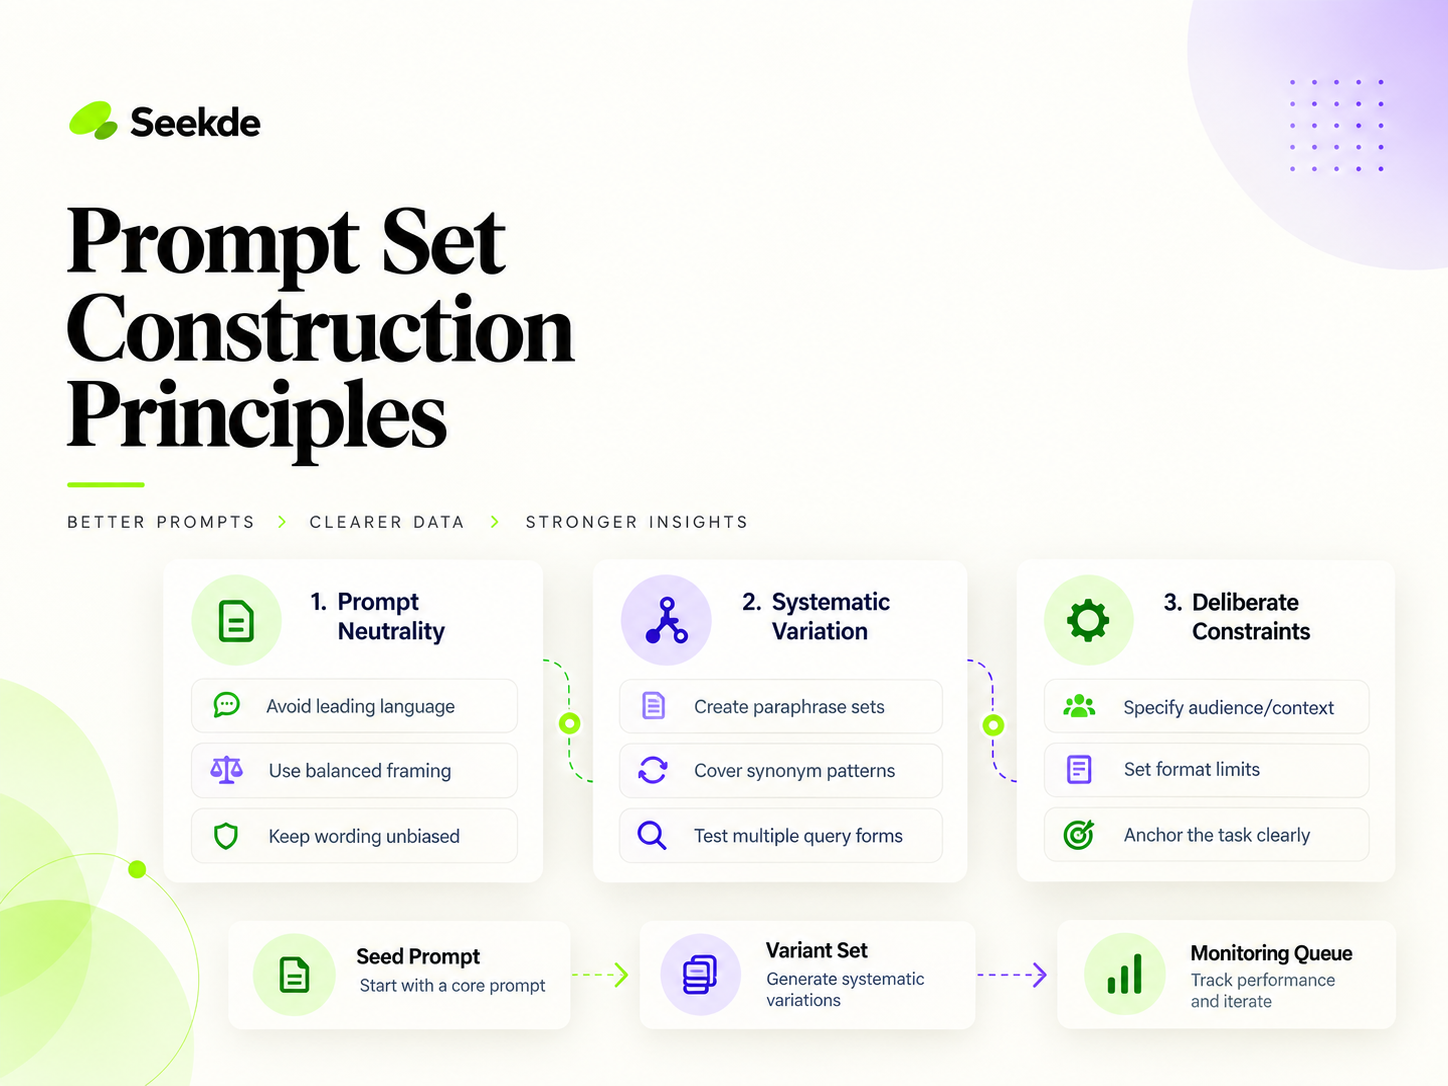
1. Absolute Prompt Neutrality
Never use leading, biased prompts that force the AI model into a predetermined response.
- Biased / Invalid: "Why is Platform X the most reliable analytics software on the market?" (Forces the engine to confirm the premise).
- Neutral / Valid: "What are the most reliable analytics platforms for high-volume ecommerce, and what are their trade-offs?"
2. Multi-Variant Syntactic Paraphrasing
A single core inquiry should be monitored across three to five linguistic variations to assess the stability of model retrieval.
For example, a core inquiry regarding CRM migration should be tested across:
- Variant A: "How difficult is it to migrate from HubSpot to Salesforce for a 50-person sales team?"
- Variant B: "HubSpot vs Salesforce migration challenges, costs, and timeline."
- Variant C: "What should a mid-market company consider when switching from HubSpot to Salesforce?"
Tracking variance across these paraphrases isolates whether your brand’s visibility is robust across diverse user prompts or fragile and dependent on exact keyword matching.
3. Deliberate Constraint Injection
Incorporate realistic operational constraints across at least 50% of your commercial prompt set:
- Scale Constraints: "for a 500-employee enterprise" vs "for a 3-person agency".
- Technical Constraints: "that supports self-hosted Docker deployments" vs "cloud-only SaaS".
- Compliance Constraints: "with native HIPAA compliance and BAA agreements".
Constraint injection reveals your true competitive boundaries: where your product wins decisively and where competitors dominate.
Recommended Sizing and Portfolio Allocation
How large should your prompt monitoring set be? Sizing depends on market maturity and organizational resources:
| Business Tier | Recommended Prompt Set Size | Intent Distribution Allocation |
|---|---|---|
| Startup / Single Product | 50 – 100 Prompts | 20% Category, 45% Commercial, 20% Comparative, 10% Navigational, 5% Operational |
| Mid-Market / Multi-Feature | 150 – 350 Prompts | 20% Category, 40% Commercial, 20% Comparative, 10% Navigational, 10% Operational |
| Enterprise / Multi-Vertical | 500 – 1,200 Prompts | 25% Category, 35% Commercial, 20% Comparative, 10% Navigational, 10% Operational |
A focused, highly relevant corpus of 100 well-engineered prompts executed across five longitudinal runs (500 total observations) yields substantially more actionable intelligence than an uncurated list of 5,000 keyword scrapes executed once.
Prompt Set Governance and Lifecycle Management
A prompt monitoring set is not a static artifact. Search queries, competitor rosters, and model architectures evolve continuously.
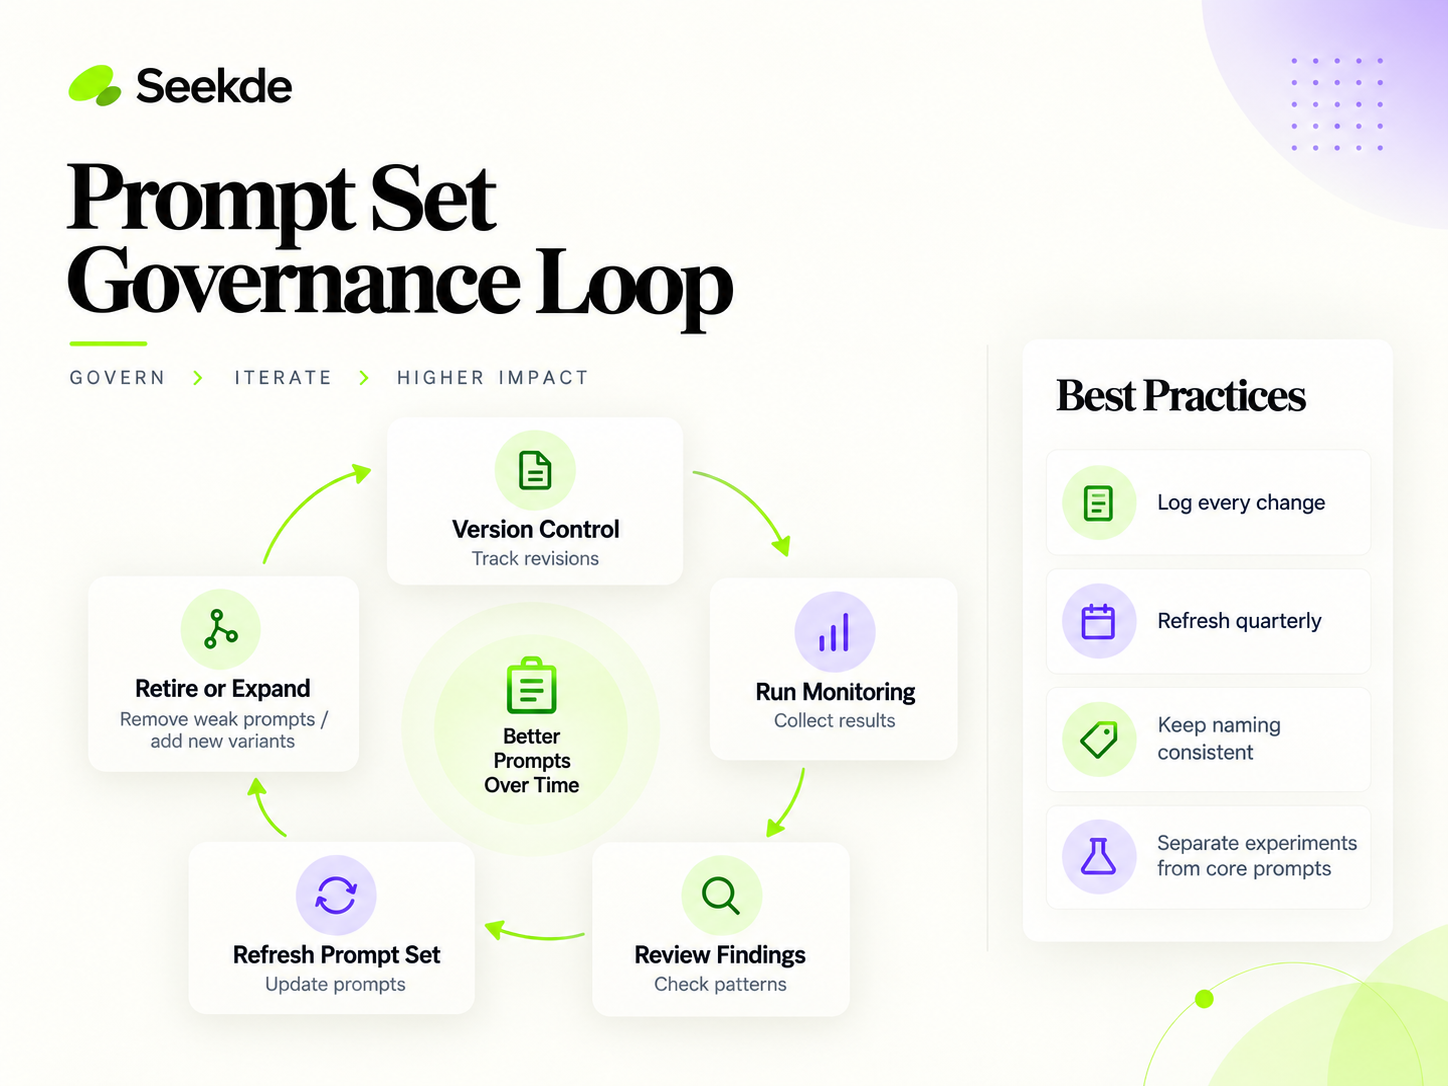
Retire obsolete features; add new market themes
v1.0, v1.1 to preserve longitudinal comparisons
Add emerging disruptors; adjust tracked rosters
1. Strict Version Control
When calculating metrics like AI Share of Voice, the denominator must remain fixed across reporting periods. If you add 50 new prompts in Month 2, you cannot compare Month 2’s aggregate SOV directly to Month 1 without re-running Month 1’s baseline.
- Maintain version-tagged prompt sets (e.g.,
Core-Prompts-v2026.1). - Archive previous versions to preserve historical audit reproducibility.
2. The Quarterly Prompt Refresh Cadence
Every 90 days, conduct a governance review:
- Retire Deprecated Topics: Remove queries referencing discontinued product tiers, legacy APIs, or acquired competitors.
- Incorporate Real-World Customer Inquiries: Mine internal sales call transcripts, customer support tickets, and on-site search logs to extract emerging natural language questions.
- Update Competitor Sets: Add emerging venture-backed competitors that have begun gaining traction in generative answers.
Next Steps: Executing Your Prompt Set
Once your prompt monitoring set is constructed and version-tagged:
- Follow the step-by-step auditing protocol in How to Measure Your Brand’s Visibility in AI Search to establish your baseline.
- Compute your initial competitive benchmark using AI share of voice formulas across direct competitors.
- Track the ratio of unlinked brand mentions versus clickable source citations as outlined in AI Citations vs Brand Mentions.
- Factor in model stochasticity and testing intervals to account for ranking volatility across evaluation runs.